
Openserp
БесплатноНе проверенSelf-hosted web search for AI agents and SEO. Google, Bing, Yandex, Baidu, DuckDuckGo & Ecosia, rendered in a real browser: ranked results and clean page Markdo

Описание
Self-hosted web search for AI agents and SEO. Google, Bing, Yandex, Baidu, DuckDuckGo & Ecosia, rendered in a real browser: ranked results and clean page Markdown. API, CLI, MCP 🎉
README
OpenSERP
Go Reference release Docker Pulls CI License: MIT Telegram
OpenSERP is a free self-hosted web search for AI agents and SEO. REST API and CLI for Google, Bing, Yandex, Baidu, DuckDuckGo and Ecosia.
No API keys, no per-search billing. It loads search results in browser and returns structured JSON with source engines and ranks. Read the linked pages as clean Markdown, or connect an agent through MCP.
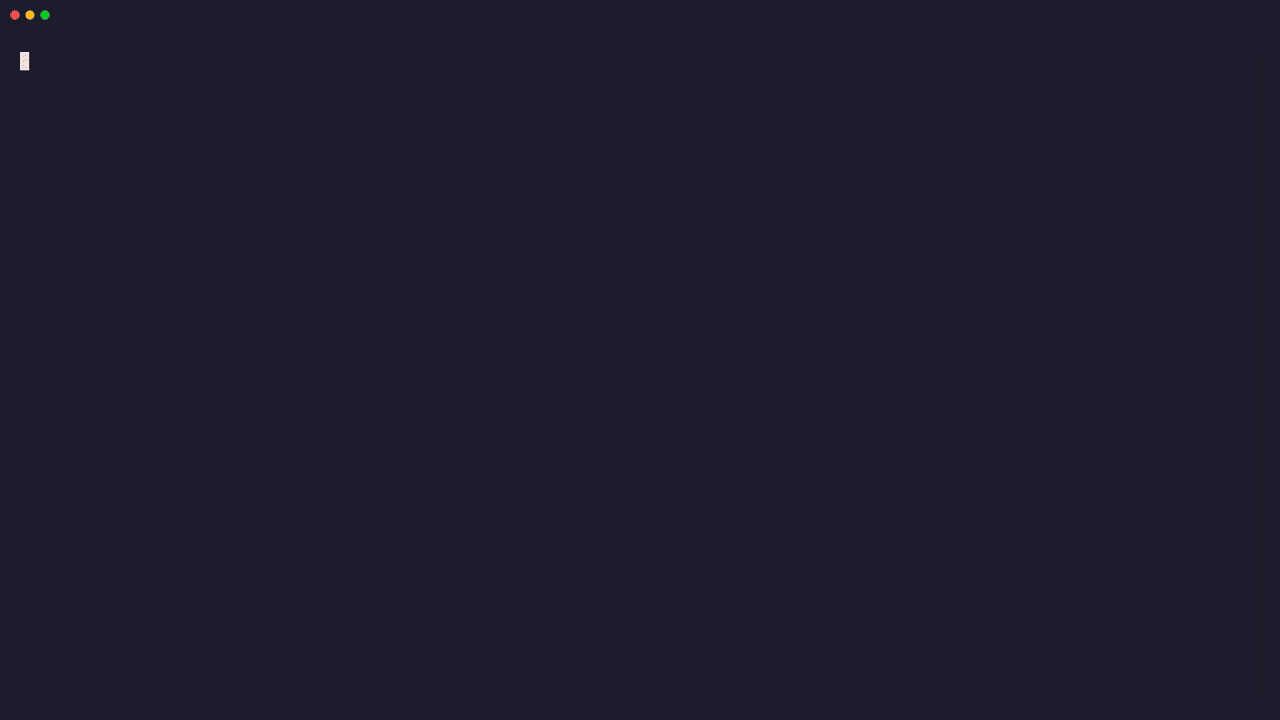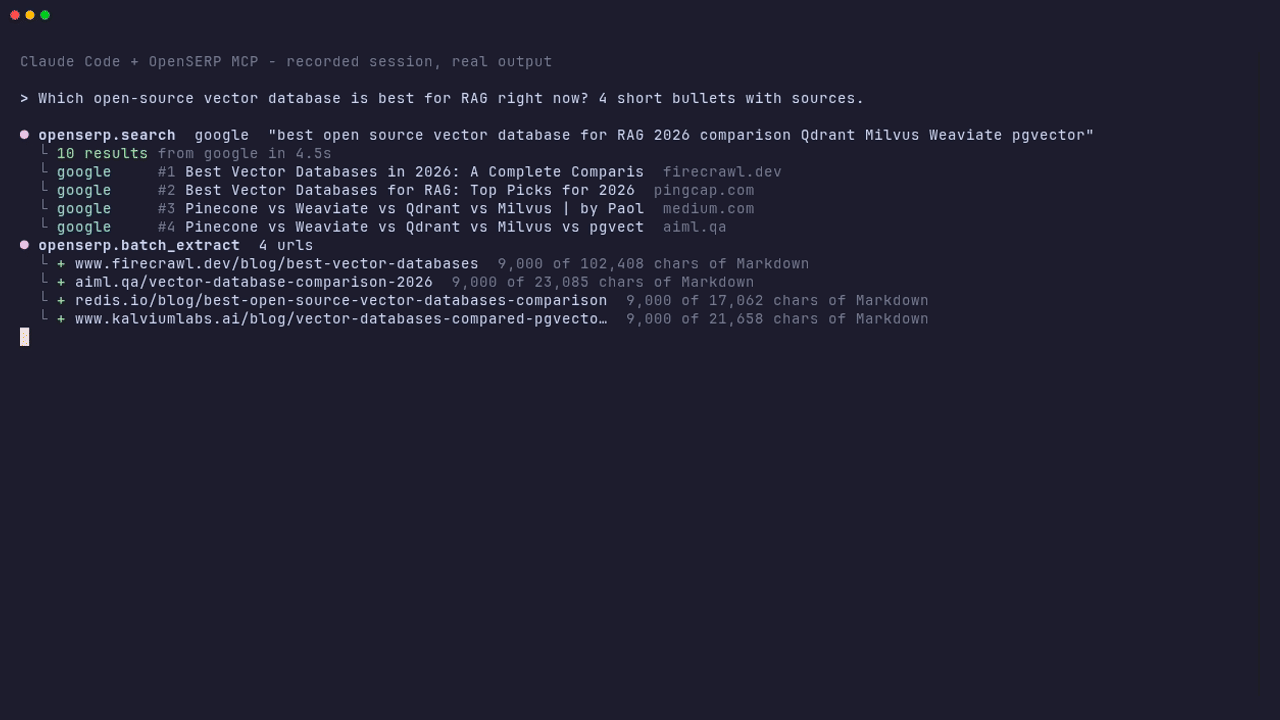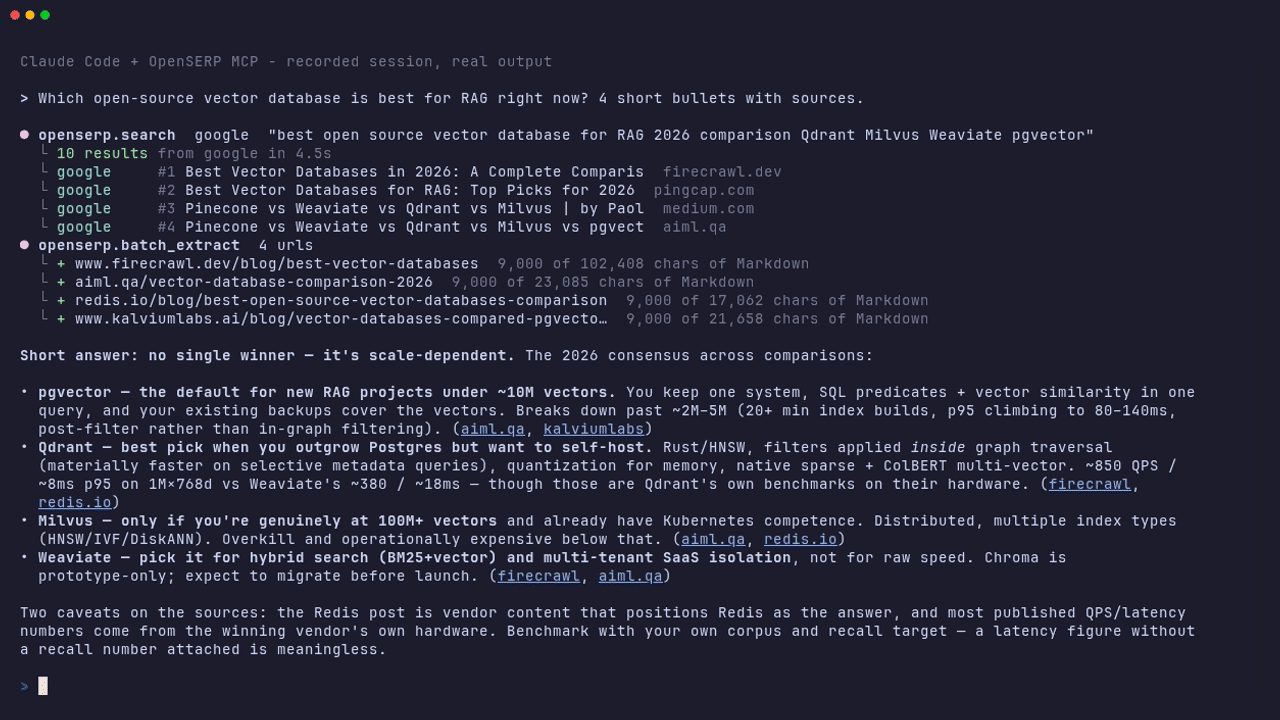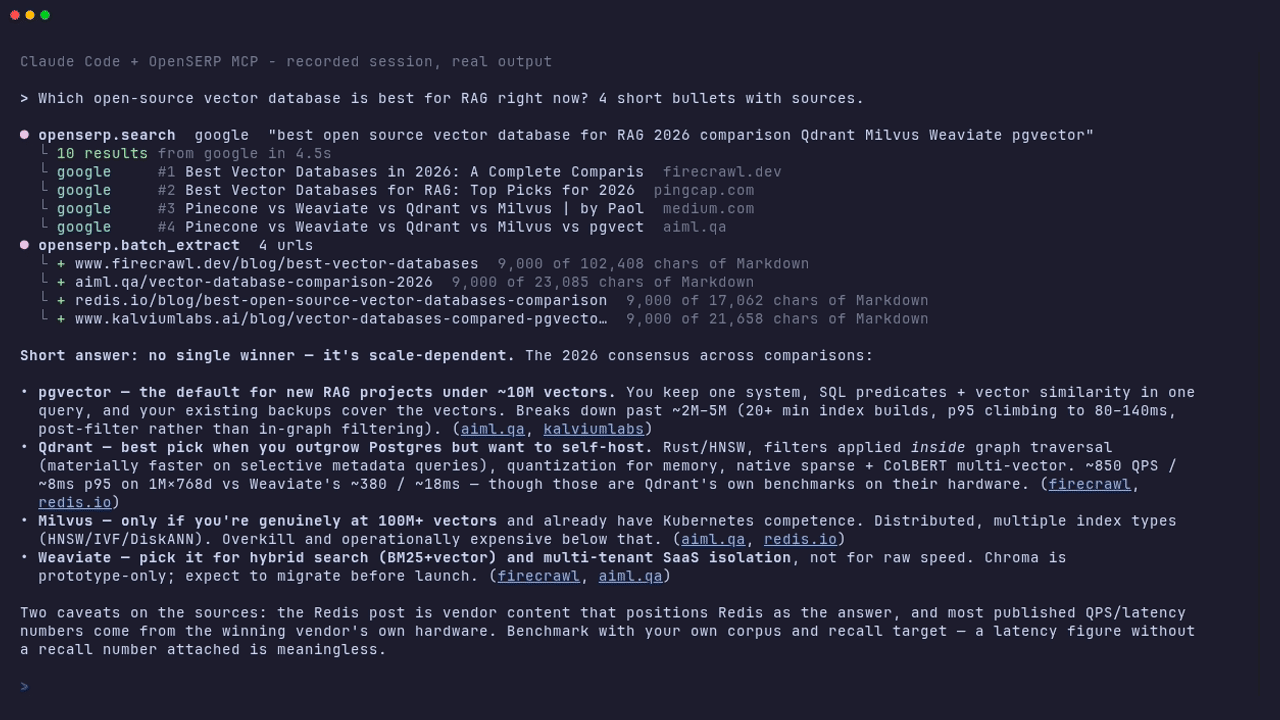
Works with Claude Code, Cursor, Codex, Claude Desktop and any MCP client, Open WebUI (built-in provider), n8n, and plain HTTP from any language.
API examples · CLI · Agent setup · API reference
Quick Start
# Start the API server
docker run --rm -p 127.0.0.1:7000:7000 karust/openserp serve -a 0.0.0.0 -p 7000

# Search Google and read the top result as Markdown
curl "http://127.0.0.1:7000/google/search?text=how+do+mcp+servers+work&extract=1"
Other ways to install
# Docker Compose
docker compose up

# Go
go install github.com/karust/openserp@latest
openserp serve

# From source
git clone https://github.com/karust/openserp.git
cd openserp && go build -o openserp . && ./openserp serve
Prebuilt binaries for Linux, macOS and Windows are on the releases page. Images: karust/openserp.
Use with AI Agents
MCP: Claude Code, Codex, Cursor, Claude Desktop
Requires Node.js 18+ and a running OpenSERP server. Add the MCP server to your client:
claude mcp add openserp -- npx -y @openserp/mcp
codex mcp add openserp -- npx -y @openserp/mcp
Cursor (~/.cursor/mcp.json), Claude Desktop, Windsurf and other clients:
{
  "mcpServers": {
    "openserp": { "command": "npx", "args": ["-y", "@openserp/mcp"] }
  }
}
On native Windows, use cmd /c npx -y @openserp/mcp after -- in the CLI commands, or "command": "cmd", "args": ["/c", "npx", "-y", "@openserp/mcp"] in JSON.
For a remote server, add "env": { "OPENSERP_BASE_URL": "http://your-host:7000" } to the openserp JSON entry.
Tools: search, mega_search, fast_search, any_search, image_search, mega_image, extract, batch_extract, list_engines. Then just ask: "Search Google for the latest Postgres release, read the top 2 results and answer with links."
Optional for Claude Code: copy skills/openserp-search to ~/.claude/skills/ so the agent searches, reads and falls back to another engine the same way every time.
Open WebUI
OpenSERP is a built-in web search provider. In Settings > Admin > Web Search pick openserp and set the URL (http://host.docker.internal:7000 if Open WebUI runs in Docker). See the Open WebUI guide.
In your own agent
A search tool for any LLM framework is a few lines with the SDK:
from openserp import OpenSERP

def web_search(query: str) -> list[dict]:
    """Search Google and return ranked results for the model."""
    with OpenSERP(base_url="http://localhost:7000") as client:
        res = client.search(engine="google", text=query, limit=10)
        return [
            {"rank": r.rank, "title": r.title, "url": r.url, "snippet": r.snippet}
            for r in res.results if r.type == "organic"
        ]
import { OpenSERP } from "@openserp/sdk";

const client = new OpenSERP({ baseUrl: "http://localhost:7000" });
const { results } = await client.search({ engine: "google", text: "openserp", limit: 5 });
| Package | Install | Source |
|---|---|---|
| @openserp/mcp - MCP server | npx -y @openserp/mcp |
openserpapi/mcp |
| @openserp/sdk - JS / TS | npm install @openserp/sdk |
openserpapi/sdk-js |
| openserp - Python | pip install openserp |
openserpapi/sdk-python |
| @openserp/n8n-nodes-openserp | Install via n8n community nodes | openserpapi/n8n |
More in examples: agent tools, RAG context, SEO rank tracking, extraction and image search.
Response Example
GET /google/search?text=how+do+mcp+servers+work&extract=1 (trimmed):
{
  "query": { "text": "how do mcp servers work", "engines_requested": ["google"] },
  "meta": { "took_ms": 4353, "engines_failed": [], "version": "2.1" },
  "results": [
    {
      "rank": 1,
      "type": "organic",
      "engine": "google",
      "title": "What Is the Model Context Protocol (MCP) and How It Works",
      "url": "https://www.descope.com/learn/post/mcp",
      "domain": "descope.com",
      "snippet": "MCP is an open standard that lets AI applications connect to external tools, data, and services through a client-server protocol built on JSON-…",
      "position": { "absolute": 1 },
      "extracted": {
        "format": "markdown",
        "content": "The Model Context Protocol (MCP) is an open standard that defines how AI applications connect to external tools, data sources, and services. MCP clients inside AI apps send requests to MCP servers, ..."
      }
    },
    {
      "rank": 2,
      "type": "organic",
      "engine": "google",
      "title": "No Dumb Questions: What is an MCP server and why do I ...",
      "url": "https://stackoverflow.blog/2026/05/08/no-dumb-questions-mcp",
      "domain": "stackoverflow.blog"
    }
  ]
}
Results keep their source engine and rank. Ads are typed separately from organic results; extract=N attaches up to N organic pages as Markdown and records per-page failures in extracted.error. Full schema in the OpenAPI spec.
Why OpenSERP
- Browser-backed search. Chromium loads the rendered SERP, including supported answer boxes, related searches and AI summaries. Raw HTTP mode is also available for Google, Yandex, Baidu and Ecosia.
- Six engines, one schema. Google, Bing, Yandex, Baidu, DuckDuckGo and Ecosia return the same JSON. Engine and rank survive a multi-engine merge, so you can see who ranked what.
- Search and read in one call.
extract=Nadds page Markdown under the top organic results,/extract/batchreads up to 20 URLs, and a dead link comes back as an error item instead of failing the batch. - Yours to run. One Go binary or Docker image, with HTTP/SOCKS5 proxies, cache, retries, rate limits and circuit breakers. No per-query fees; you cover compute and proxies.
Compared to Paid Search APIs
| Feature | OpenSERP | Cloud | Tavily | SerpApi | Exa |
|---|---|---|---|---|---|
| Google results | ✅ | ✅ | 🟨 Undisclosed | ✅ | ❌ |
| Search engines | 6 | 6 | Own retrieval | Many | Exa index |
| Original engine ranks | ✅ | ✅ | ❌ | ✅ | ❌ |
| Page extraction | ✅ Markdown, batch | ✅ Markdown, batch | ✅ | ✅ | ✅ |
| Self-hosting | ✅ | ❌ | ❌ | ❌ | ❌ |
| SEO monitoring, rank tracking | 🟨 | ✅ | ❌ | 🟨 | ❌ |
| PR monitoring, competitor tracking | 🟨 | ✅ Beta | 🟨 | 🟨 | ✅ API |
| AI reports and alerts | 🟨 | ✅ | 🟨 | 🟨 | 🟨 |
| Pricing | Free + infrastructure | PAYG, $0.0078/credit | $30/mo, 4k basic credits | $25/mo, 1k searches | PAYG, $4/1k Lite searches |
✅ Available · 🟨 Partial, unconfirmed or requires integration · ❌ Unavailable
Search Endpoints
Engine names: google, yandex, baidu, bing, duckduckgo (also duck, ddg), ecosia.
Use a dedicated endpoint when the source engine matters, any for ordered fallback, or balanced to compare engines. Search supports JSON, Markdown, text and NDJSON, plus language, region, date, site and file filters.
Dedicated engine endpoints:
curl "http://127.0.0.1:7000/google/search?text=golang&limit=10"
Image search:
curl "http://127.0.0.1:7000/bing/image?text=golang+logo&limit=10"
Megasearch:
curl "http://127.0.0.1:7000/mega/search?text=golang&limit=10"
/mega/search returns the same envelope as engine endpoints plus clusters: results are deduplicated by normalized URL, and clusters keep the per-engine occurrences and ranks.
| Mode | Best for | Behavior |
|---|---|---|
balanced |
Most multi-engine SERP workflows | Queries engines in parallel and merges results |
fast |
One engine selected by latency history | Uses one engine; does not fall back on failure |
any |
Ordered fallback | Tries engines in order until one succeeds, even with zero results |
More megasearch examples
# Fast mode
curl "http://127.0.0.1:7000/mega/search?text=golang&mode=fast&engines=google,bing,yandex"
# Any mode
curl "http://127.0.0.1:7000/mega/search?text=golang&mode=any&engines=google,yandex,bing"
# Balanced mode with aggregation controls
curl "http://127.0.0.1:7000/mega/search?text=golang&mode=balanced&dedupe=true&merge=true"
# Advanced filtering
curl "http://127.0.0.1:7000/mega/search?text=golang&engines=google,bing&limit=20&date=20250101..20251231&lang=EN®ion=US"
# Image megasearch
curl "http://127.0.0.1:7000/mega/image?text=golang+logo&limit=20"
List engines:
curl "http://127.0.0.1:7000/mega/engines"
URL extraction:
# Extract one URL as JSON
curl "http://127.0.0.1:7000/extract?url=https://example.com&mode=auto"

# Return clean page markdown
curl "http://127.0.0.1:7000/extract?url=https://example.com&format=markdown"

# Extract several URLs at once - returns a bare [{page_content, metadata}] array
# (Open WebUI external loader compatible); failed URLs become items with metadata.error
curl -X POST "http://127.0.0.1:7000/extract/batch" \
  -H "Content-Type: application/json" \
  -d '{"urls":["https://example.com","https://go.dev"],"mode":"fast"}'

# Embed extracted content under the top organic results
curl "http://127.0.0.1:7000/google/search?text=llm+observability&extract=2&format=markdown"
CLI Search
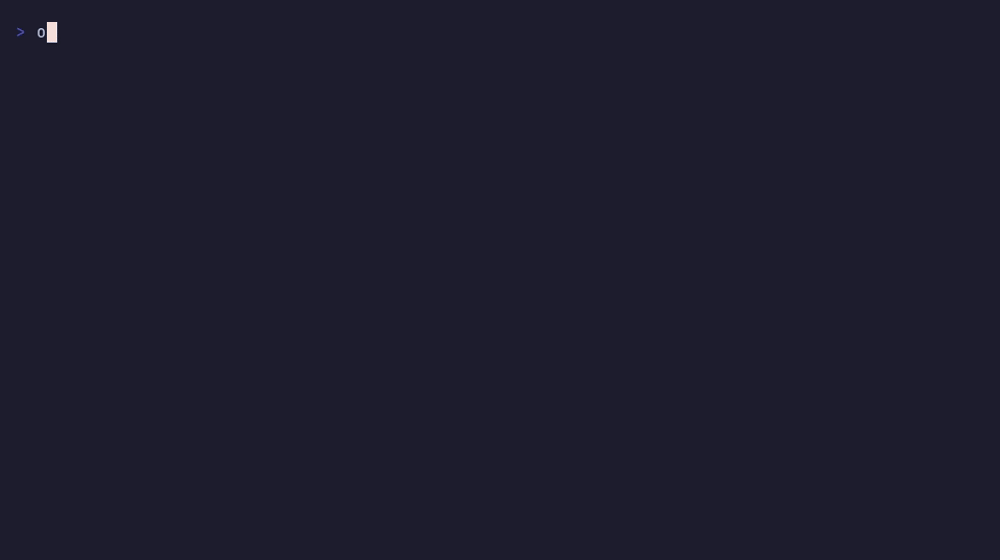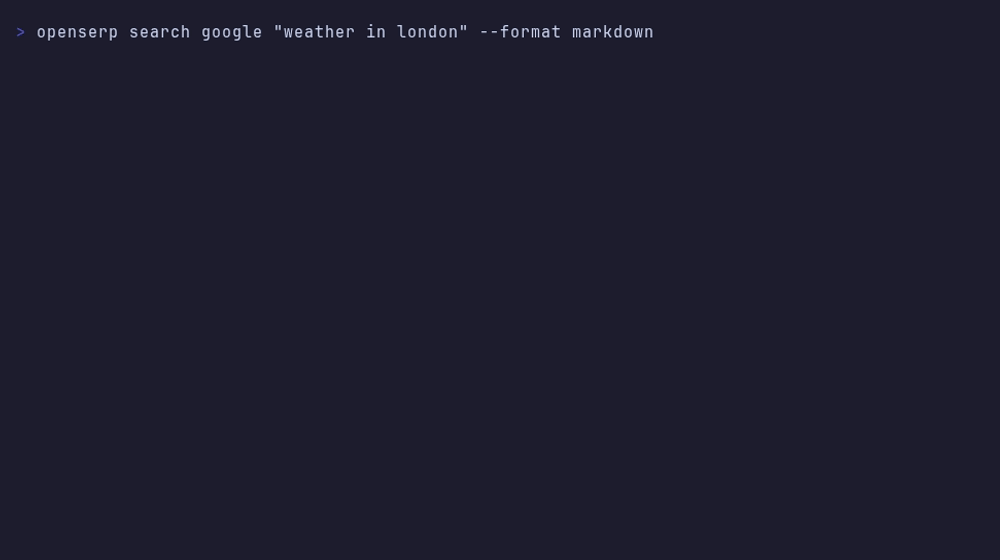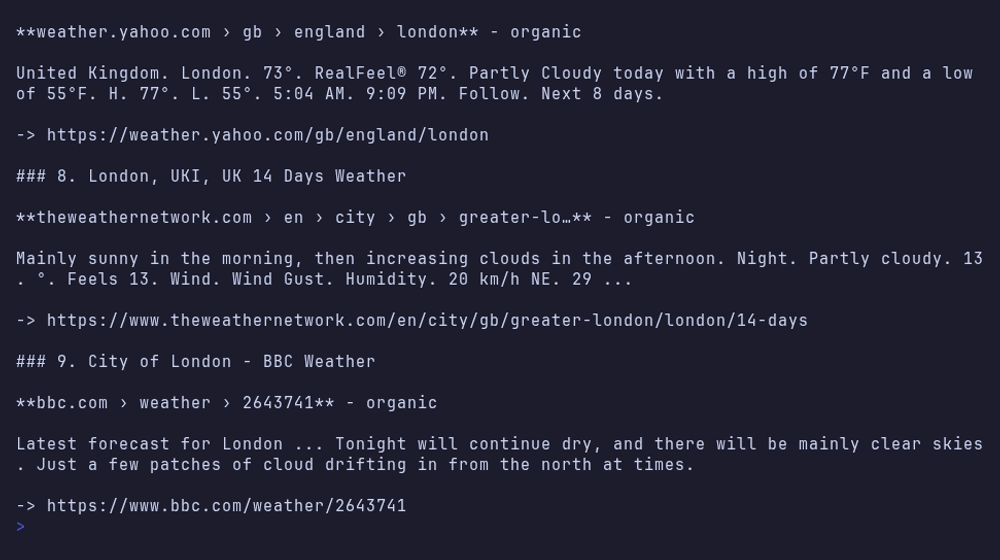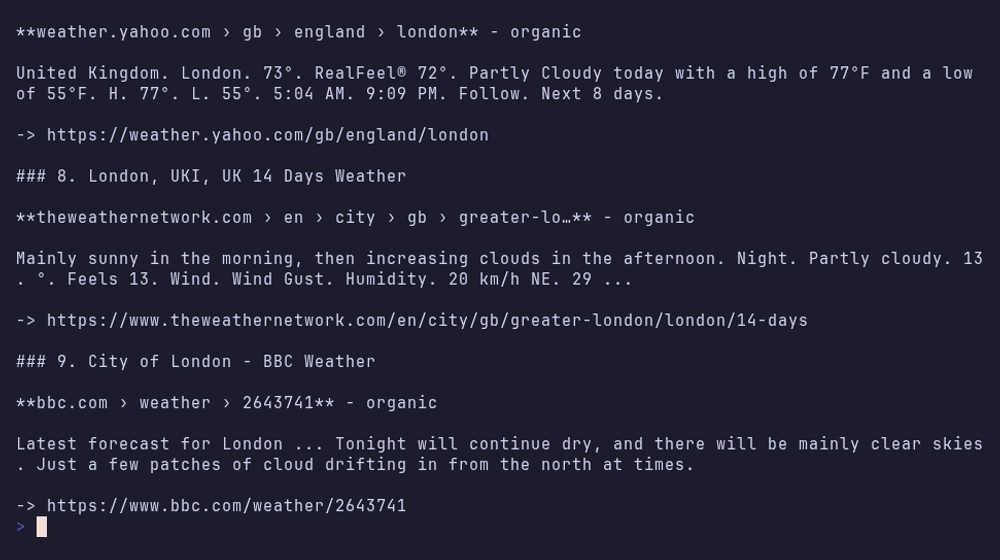
No server required - query an engine straight from the terminal. The CLI shares the same engines, formats, and filters as the API.
openserp search ecosia "weather in london" --format markdown
CLI output and more examples
# Search results for "weather in london"

**Query:** weather in london - **Engines:** ecosia - **Took:** 866ms

## Results

### 1. London - BBC Weather

**bbc.com › weather › 2643743** - organic

Latest forecast for London ... Tonight will continue dry, and there will be mainly clear skies. Just a few patches of cloud drifting in from the north at times.

-> https://www.bbc.com/weather/2643743

### 2. London (Greater London) weather - Met Office

**weather.metoffice.gov.uk › forecast › gcpvj0v07** - organic

Remaining warm with light winds and dry. Possibly cloudy at times Monday and Tuesday, then Wednesday sunnier conditions are likely.

-> https://weather.metoffice.gov.uk/forecast/gcpvj0v07
More CLI examples:
# JSON is the default format
openserp search google "golang generics" --limit 20

# Plain text, German results
openserp search yandex "wetter berlin" --format text --lang DE --region DE

# Restrict to a site and stream NdJSON
openserp search bing "release notes" --site github.com --format ndjson

# Embed clean page content from the top 2 organic results
openserp search google "llm observability" --extract 2 --format markdown

# Browserless (raw HTTP) mode through a proxy
# (raw mode: google, yandex, baidu, ecosia)
openserp search ecosia "weather in london" --raw --proxy http://user:[email protected]:8080
Run openserp search --help for the full flag list. Results go to stdout, logs to stderr. Set verbosity with --log_level error|warn|info|debug|trace or OPENSERP_APP_LOG_LEVEL (CLI default: warn). serve also writes ./logs.txt unless app.save_log: false.
Query Parameters
Common parameters
| Parameter | Description | Example |
|---|---|---|
text |
Search query | golang programming |
lang |
Language code | EN, DE, RU, ES |
region |
Market/location hint. Countries/locales work across engines; Google also accepts city names via uule; Yandex accepts numeric lr. |
DE, en-GB, Berlin, 213 |
date |
Date range | 20250101..20251231 |
file |
File extension | pdf, doc, xls |
site |
Site-specific search | github.com |
limit |
Number of organic results, max 100. When omitted or <=10, only the first SERP page is parsed. |
25, 50 |
start |
Pagination offset | 0, 10, 20 |
format |
Output format | json, markdown, text, ndjson |
extract |
Fetch and embed target-page content for organic results. Ads and answer rows are skipped. 0/false off, true/1 top organic result, N up to N (1-5). extract_mode/min_runes imply extract=true unless extract=0 |
1, 3, true |
extract_mode |
Extraction strategy: raw HTTP first, raw only, or browser-rendered | auto, fast, rendered |
Engine-specific parameters
| Parameter | Supported engines | Notes |
|---|---|---|
filter |
google |
Duplicate filter: true hides similar results, false includes them. |
features |
browser Search |
Populate serp_features[] from the live page. Defaults to true. |
resolve_urls |
google |
Turn Google /goto redirect links into destination URLs (one redirect hop, ads skipped). true (default), false, or top N. |
Bing localizes by exit IP. lang sets its interface language; region sends a country hint except for US, CN and RU, which caused unrelated results in testing. For those locations, use a proxy in the target country.
Proxy Support
OpenSERP supports HTTP and SOCKS5 proxies.
./openserp serve --proxy socks5://127.0.0.1:1080
./openserp search bing "query" --proxy http://user:[email protected]:8080
Engines can return CAPTCHAs, rate limits or unrelated results. Browser mode does not eliminate these; try another engine or a proxy when needed.
Advanced proxy configuration is available in config.yaml. You can enable tagged proxy pools and per-request override via X-Use-Proxy: <tag> or X-Use-Proxy: direct.
API Docs
Once the server is running, the interactive docs are available locally:
- Swagger UI:
http://127.0.0.1:7000/docs- full schemas, error shapes, and the/health,/ready,/stats/*endpoints - OpenAPI YAML:
http://127.0.0.1:7000/openapi.yaml
To browse the spec without running the server, see docs/openapi.yaml. For how OpenSERP works internally, see the architecture docs.
Contributing
Contributions are welcome. See docs/CONTRIBUTING.md.
License
MIT. See LICENSE.
Feedback & Updates
- GitHub Issues - bugs, feature ideas, and reproducible issues.
- [email protected] - private notes, longer feedback, or anything that does not fit GitHub Issues.
- Telegram - OpenSERP news, release notes, and project updates.
OpenSERP is free and open-source. Only links listed in this repository and on openserp.org are associated with the project.
Установка Openserp
У этого сервера нет опубликованного пакета — он собирается из исходников. Открой репозиторий и следуй инструкции в README.
▸ github.com/karust/openserpFAQ
Openserp MCP бесплатный?
Да, Openserp MCP бесплатный — установка в пару кликов через Unyly без оплаты.
Нужен ли API-ключ для Openserp?
Нет, Openserp работает без API-ключей и переменных окружения.
Openserp — hosted или self-hosted?
Self-hosted: сервер запускается локально на твоей машине командой из раздела установки.
Как установить Openserp в Claude Desktop, Claude Code или Cursor?
Открой Openserp на unyly.org, выбери вкладку своего клиента (Claude Desktop, Claude Code, Cursor) и нажми Install — конфиг сгенерируется автоматически, без правки JSON.
Похожие MCP
Playwright
Browser automation, scraping, screenshots
 автор: Microsoft
Puppeteer
Browser automation and web scraping.
 автор: modelcontextprotocol
Garmin Connect
An MCP server for Garmin Connect that provides access to fitness activities, health statistics, and sleep data by routing requests through a headless browser to
 автор: etweisberg
Higgsfield Unlimited
MCP server for Higgsfield AI that enables unlimited-mode image, video, audio generation, uploads, and job management via multiple parallel accounts, using brows
 автор: nukIeer
opentabs-dev/opentabs
Plugin-based server and Chrome extension that gives AI agents access to web apps through your authenticated browser session, with a plugin SDK.
 автор: opentabs-dev
hlydecker/ucsc-genome-mcp
Interact with the UCSC Genome Browser API to find genomes, chromosomes and more.
 автор: hlydecker
34892002/bilibili-mcp-js
Search Bilibili content, with LangChain integration examples.
 автор: 34892002
achiya-automation/safari-mcp
Native Safari browser automation without a Chrome dependency.
 автор: achiya-automation
agent-infra/mcp-server-browser
Browser automation using Puppeteer, supporting local and remote browser connections.
 автор: bytedance
aparajithn/agent-scraper-mcp
Web scraping: clean content extraction, CSS-selector scraping, Playwright screenshots, link and metadata extraction, and Google search.
 автор: aparajithn
Compare Openserp with
Не уверен что выбрать?
Найди свой стек за 60 секунд
Автор?
Embed-бейдж для README
Похожее
Все в категории browse