
Super Loop
БесплатноНе проверенA referee for self-improving AI agent loops that mines past sessions for effective workflows, improves them, and requires measured proof before declaring anythi

Описание
A referee for self-improving AI agent loops that mines past sessions for effective workflows, improves them, and requires measured proof before declaring anything better or done, never stopping until the user stops it.
README
Make AI agents prove they got better.
Loop Factory is a local MCP server and autonomous CLI that continuously finds workflows, proposes improvements, tests the original against the challenger, and sends measured winners to an approval desk.
It is a deterministic slop terminator: models can propose anything, but claims, self-reported scores, and confident summaries do not count as progress.
What It Does
mine a real workflow
        |
freeze the original and benchmark
        |
generate competing revisions
        |
test original, challenger, and controls
        |
re-open saved outputs and recalculate the result
        |
queue measured winners for Approve or Deny
        |
continue to the next target until the operator stops it
Pending reviews do not pause the factory. A model cannot promote itself. The operator is the only stop condition.
Recursive Harness V2
The current build can also improve the mechanism it uses to propose later improvements. It does this conservatively:
- one model proposes at most three typed changes to a deterministic mechanism;
- five tasks calibrate real candidate movement against an irrelevant sham;
- only a qualified calibration unlocks five untouched confirmation tasks;
- three replicates per arm produce 60 calls per stage;
- the verifier reopens every saved prompt, receipt, candidate, and evaluation;
- a passing descendant enters bounded routing, never canonical promotion; and
- the next generation receives an immutable receipt explaining the measured mechanism, result, placebo movement, regressions, and evidence hashes.
Context allocation can move only 10% after five valid token observations. Mechanism records are never deleted or summarized for savings; an oversized prompt may use a hash-bound, lossless index while full bytes remain on disk. Related, adjacent, failure-derived, wildcard, and permanent no-memory control slots remain deterministic and replayable.
This implementation is locally tested. It is not presented as scientifically proven until a separately approved live campaign passes the same verifier on real disjoint tasks. See Recursive Harness V2.
What The Final Run Proved
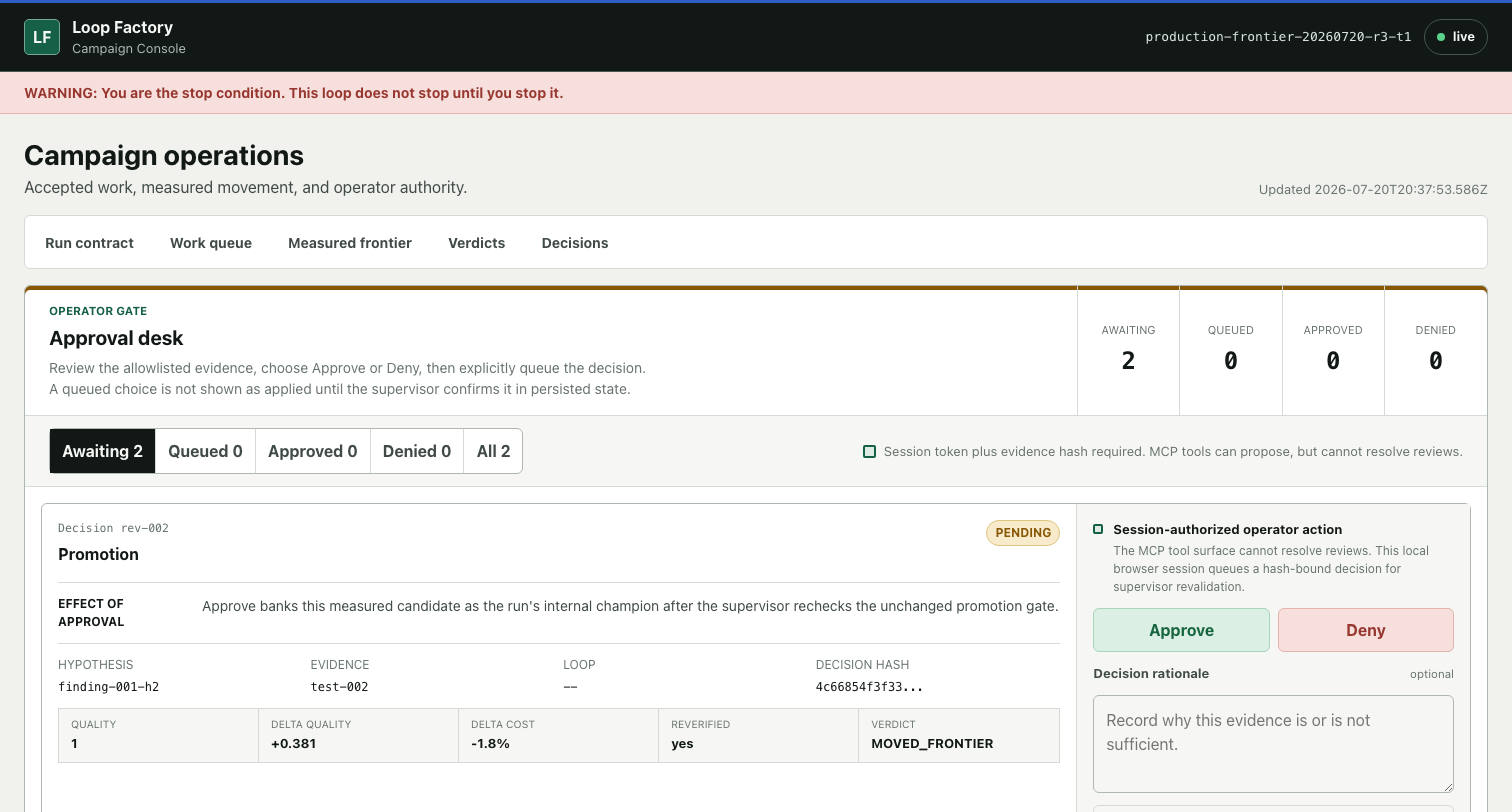
The final Build Week run found a real workflow for deciding whether a revision should move forward, then tested two meaningful rewrites from scratch.
| Procedure | Quality | Mean CLI tokens | Quality change | Cost change |
|---|---|---|---|---|
| Original | 0.6190 |
61,270.3333 |
baseline | baseline |
| H1: clear acceptance rules | 1.0000 |
60,180 |
+0.3810 |
-1.78% |
| H2: evidence and recheck rules | 1.0000 |
60,193.3333 |
+0.3810 |
-1.76% |
The run used:
12real model calls;- exact
gpt-5.6-solat high reasoning; - zero retries and zero exit failures;
12isolated workspaces;724,453CLI-reported tokens;34/34saved-file hash checks; and- a separate verifier that returned
PASS.
Both revisions remain pending in the approval desk. No promotion was recorded. H1 is the measured recommendation, not an automatic decision.
Read the production report or compare the original with the recommended revision.
Verify It In 30 Seconds
Requirements: Node.js 18 or newer.
git clone https://github.com/alexalexalex222/Loop-Factory-mcp-public.git
cd Loop-Factory-mcp-public
npm run verify:submission
Expected top-level result:
{
  "status": "PASS"
}
This command makes no model call. It:
- re-derives a public 16-call controlled proof run from saved transcripts;
- checks five paired challenger wins, zero wins by the irrelevant-edit control, and zero regressions;
- verifies model selection, retries, isolated workspaces, output formats, token counts, and file hashes; and
- integrity-checks the final production evidence.
It exits nonzero if any gate fails.
Current Model Policy
The default policy now uses the current routes exercised by this project:
| Role | Default |
|---|---|
| Primary worker | gpt-5.6-sol |
| Test routes | gpt-5.6-sol, claude-fable-5, gpt-5.6-terra |
| Drafting and gate checks | claude-fable-5, gpt-5.6-sol |
| Independent judge | claude-fable-5 |
Claude workers are launched with an explicit --model flag. Codex workers are
launched with an explicit -m flag. The operator may replace the full policy
when starting a run. Strict proof runs can lock every call to one
exact model, as the final GPT-5.6 Sol production run did.
Optional Improvement Memory
Loop Factory records deterministic improvement receipts and can use them in two
off-by-default modes. shadow writes an auditable ranking packet without
changing execution. active-canary routes only reverified, control-complete
harvest evidence before hypothesis generation, preserves a permanent no-memory
control, compiles executable mechanisms before registration, and binds every
affected hypothesis to the exact route, policy, capsule, treatment, and
interface hashes.
Active routing is not permission to call a result an improvement. Automatic banking remains closed until the supervisor receives sealed paired baseline/routed/sham evidence with zero sham movement, zero control regressions, complete transfer evidence, and every existing promotion gate. The operator API accepts persisted measurement references, never caller-supplied quality numbers. A restart resumes registered pending hypotheses without rerunning the frozen baseline; unused routes require an immutable operator retirement receipt.
The operator can also import a persisted V4 executable-canary pass. The import reruns the independent verifier, pairs only the shared confirmation tasks, and stores a routing-only receipt; it never updates policy, promotion, or canonical loop bytes. Automatic import additionally requires a predeclared sealed config flag. When that flag is present, the executable-canary CLI performs the import before reporting closed-loop success. A causal PASS whose verifier-owned import fails exits nonzero; a valid causal FAIL remains evidence and imports nothing.
The autonomous campaign CLI also persists a private, hash-chained parent scheduler ledger. Queue state, the active target and deterministic child run ID, coverage, counters, deduplication sets, promotion state, and idle/mining epochs survive a cold process restart. The exact campaign config is hash-bound to every checkpoint, completed child receipts are reopened without another worker call, and config or ledger drift fails closed.
The feature is off by default. Enable it in initialize_loop_run:
{
  "config": {
    "metaLearning": {
      "enabled": true,
      "mode": "shadow",
      "policyId": "meta-policy-v1",
      "seed": "run-bound-safe-id"
    }
  }
}
Autonomous campaign configs place the same object under
engineConfig.metaLearning. See
the improvement memory contract for receipt,
partition, fallback, privacy, and claim boundaries, and
the adaptive intelligence contract for the
active-canary safety boundary.
Run The Factory
The autonomous driver is opt-in because it launches real model workers:
SUPER_LOOP_ALLOW_EXEC=1 npm run run-campaign -- \
  --config examples/campaign.json \
  --stop-file ./STOP \
  --dashboard-port 8787
Open http://127.0.0.1:8787 for the campaign and approval dashboard.
Create the stop file when you want the factory to stop:
touch STOP
The example campaign uses GPT-5.6 Sol, Fable 5, and GPT-5.6 Terra. Edit the config before running if you want a narrower policy or a different target.
Use It As An MCP Server
Point an MCP-capable host at src/server.mjs:
{
  "mcpServers": {
    "loop-factory": {
      "command": "node",
      "args": ["/absolute/path/to/Loop-Factory-mcp-public/src/server.mjs"],
      "env": {
        "SUPER_LOOP_HOST": "codex"
      }
    }
  }
}
Start with initialize_loop_run. Loop Factory asks for the goal, starting
path, benchmark, limits, and model policy once, then persists the campaign.
What It Refuses To Trust
- A worker saying its own revision is better.
- A score typed by a model instead of derived by the tool.
- A challenger tested against a conveniently weak baseline.
- A result without both the original output and the parsed result.
- A requested model that differs from the sealed plan.
- A measured win that has not been checked again from saved evidence.
- A model attempting to approve or promote its own work.
Useful Commands
| Command | Purpose |
|---|---|
npm run verify:submission |
Re-run the public judge proof with no model call |
npm test |
Run the complete test suite |
npm run verify |
Verify the bundled loop hashes |
npm run demo |
Generate a deterministic local demo |
npm run run-campaign -- --config <file> |
Start the autonomous factory |
npm run verify:run -- --home <home> --run <id> |
Recompute a persisted production run |
npm run judge:gpt56-sol |
Run the optional exact-model enforcement proof |
Evidence
- Judge guide
- Production evidence
- Portable controlled proof run
- Real-test design
- Improvement memory contract
- Submission copy
- Video script
Honest Boundaries
- The production evidence publishes privacy-safe results and hashes, not raw provider transcripts containing machine-specific paths.
- The public controlled proof run includes transcript-backed evidence and is the fully portable no-model verification path.
- The production run proved one mined workflow improved under its frozen benchmark. It does not prove every possible workflow will improve.
- Model availability depends on the operator's authenticated Claude Code and Codex installations.
- Loop Factory records a winner only after operator approval. It does not overwrite canonical user files.
SUPER_LOOP_HOME is always authoritative. Existing <package>/.super-loop
state remains discoverable and is never moved automatically. A source checkout
keeps that historical default; a fresh packed installation uses the writable
per-user location listed below. The selected path and its source are printed at
server startup.
| Platform | Fresh installed state path |
|---|---|
| macOS | ~/Library/Application Support/Loop Factory |
| Linux | $XDG_STATE_HOME/loop-factory, or ~/.local/state/loop-factory |
| Windows | %LOCALAPPDATA%\Loop Factory |
The autonomous driver is opt-in. Without the exact value
SUPER_LOOP_ALLOW_EXEC=1, Loop Factory does not launch workers.
POSIX shell:
SUPER_LOOP_ALLOW_EXEC=1 node scripts/run-campaign.mjs --config examples/campaign.json --stop-file ./STOP
touch ./STOP
PowerShell:
$env:SUPER_LOOP_ALLOW_EXEC = "1"
node scripts/run-campaign.mjs --config examples/campaign.json --stop-file .\STOP
New-Item -ItemType File .\STOP
Windows Command Prompt:
set "SUPER_LOOP_ALLOW_EXEC=1"
node scripts\run-campaign.mjs --config examples\campaign.json --stop-file .\STOP
type nul > .\STOP
Start the local dashboard with node scripts/dashboard-server.mjs; pass
--home "<path with spaces>" when selecting state explicitly. Run
npm run package:smoke to pack, install into a clean path containing spaces,
handshake the installed MCP, verify all tools and loop hashes, and round-trip
isolated state.
On Windows, JSON configuration paths need escaped backslashes (or forward slashes), for example:
{
  "command": "node",
  "args": ["C:\\Users\\Ace\\Loop Factory\\src\\server.mjs"],
  "env": { "SUPER_LOOP_HOST": "codex" }
}
Core platform evidence
CI PASS means the flow passes the public repository's
Portability workflow
on GitHub-hosted runners. Provider authentication is a separate boundary.
| OS | Core package/install | MCP stdio | Persistence | Dashboard | Autonomous supervisor | Fake executor | Authenticated Claude CLI | Authenticated Codex CLI | Authenticated OpenCode routes |
|---|---|---|---|---|---|---|---|---|---|
| macOS | CI PASS | CI PASS | CI PASS | CI PASS | CI PASS | CI PASS | not retested here | one live executor audit | not verified |
| Ubuntu | CI PASS | CI PASS | CI PASS | CI PASS | CI PASS | CI PASS | not verified | not verified | not verified |
| Windows | CI PASS | CI PASS | CI PASS | CI PASS | CI PASS | CI PASS | not verified | not verified | not verified |
The workflow also checks Node 18, 22, and 24 on Ubuntu, matching the existing
node >=18 package declaration. Profiles in
hosts/registry.json remain labeled independently from
core OS support.
Optional live path
Judges with GPT-5.6 Sol access can run:
npm run judge:gpt56-sol
This pins gpt-5.6-sol, refuses fallback, and runs three controlled enforcement
fixtures: PHASE_SKIP, MODEL_REPORTED_METRIC, and SELF_PROMOTION. Those are
adversarial regression prompts, not claims of spontaneous model behavior.
What changed on July 18, 2026
Build Week added the exact GPT-5.6 Sol route and invocation receipts, the one-command live judge kit, the Campaign Console, and the controlled adversarial fixtures above. The July 19 causal canary added paired baseline/challenger/sham evidence and fresh-checkout re-verification. The July 20 production frontier run then demonstrated the complete mine-to-measure-to-review workflow on a real mined procedure without weakening operator-owned promotion.
Evidence index
- Public causal canary: submission/evidence/context-isolation-canary-20260719/
- Production frontier packet: submission/evidence/production-frontier-20260720/
- Deterministic verifier: scripts/verify-submission.mjs
- Tamper regression:
test/submission-verifier.test.mjs - Judge guide: docs/JUDGE_GUIDE.md
- Controlled enforcement transcript:
proof/build-week/gpt56-sol-live-20260718-final/TRANSCRIPT.md - Campaign Console browser QA:
proof/build-week/campaign-console-20260718-final/qa-summary.json
For developers
Engineering detail: tools, host matrix, trajectory export, layout, and block codes.
Host compatibility
Loop Factory is MCP-first, with the continuous driver chosen per host from hosts/registry.json, and scripts/run-campaign.mjs as the universal fallback.
| Host | Driver family | Tier | Continuous driver | Verified |
|---|---|---|---|---|
| Codex | goal_progress |
1 | /goal |
✅ |
| Claude Code | goal_progress |
1 | /goal (operator-stop objective) |
✅ |
| ZCode | goal_progress |
1 | /goal (mirrors Codex — confirm) |
⚠︎ |
| OpenCode | plugin_goal |
1 | /goal (requires a goal plugin) |
⚠︎ |
| Cursor | mcp_reactive |
2 | none — continuation rules snippet | ⚠︎ |
| Kilo Code | mcp_reactive |
2 | none — rules snippet (CLI fork = tier 1 with a goal plugin) | ⚠︎ |
| OpenClaw | auto_continue |
2 | config (autoContinue / heartbeat) |
⚠︎ |
| Factory Droid | orchestrator |
2 | Super Loop runs inside a Mission worker | ⚠︎ |
| Hermes | internal_loop |
3 | its own loop — call tools each turn | ⚠︎ |
| MiniMax Mini-Agent | internal_loop |
3 | its own loop, or the CLI fallback | ⚠︎ |
| anything else | cli_autonomous |
3 | super-loop-run (universal fallback) |
— |
Three tiers (per hosts/registry.json):
- Native goal (Codex, Claude Code, ZCode, OpenCode+plugin) — engage
/goalwith an operator-stop objective. - MCP + continuation contract (Cursor, Kilo IDE, OpenClaw, Factory Droid) — no reliable continuous slash command; ship the continuation rules snippet.
- Internal loop or CLI (Hermes, Mini-Agent,
super-loop-run) — host owns its loop, or drive headless with the CLI.
⚠︎ verified:false entries are modeled from the design — confirm the exact command in your build. host_capability_preflight returns the resolved host profile (tier, driverFamily, setupHint).
Why this exists
Drop a 300+ line loop into a model's context and it may ingest the whole thing, skip the structure, and treat an unverified argument as a test. Loop Factory fixes that with hard mechanics:
Ask-once — starts with a brief explanation plus a few short questions once:
- the goal;
- the path — improve a loop you already run, discover/find a loop (optionally scouting a public loop library), or mine your whole history (deep);
- the loop or domain to start from;
- corpus scope — your whole session history or a set number of loops, and best-first vs in-order (asked with an up-front warning that a run can take hours, days, or weeks depending on how deep it mines);
- what "better" means (this becomes the frozen benchmark);
- any task-specific limit;
- which models to use (primary, optional test/builder/judge routes — press enter for defaults, or say
any modelto disable the banlist for this run); - and a final deeper-explanation offer, honored in the same response.
You choose the models at init (defaults:
gpt-5.6-solprimary, builders Fable 5 / GPT-5.6 Sol, standard frontier test set). The supervisor still owns measurement, integrity, and promotion — it never asks about promotion mode or benchmark policy. Afterward it does not ask again or mark the campaign complete by itself. A fresh run also carries a cold-start notice: don't resume a prior campaign or assume a path from memory — infer only from this message and the answers (pass arunIdto resume on purpose).Phase-gated streaming — holds the loop inside the MCP and hands you the next section only after the current one has recorded evidence. No 1k-line dump.
Benchmark-first — the baseline is hash-locked and the scorecard is frozen before any challenger. Model self-reported metrics never count.
Hypothesis engine — full tests need 3–5 hypotheses on routes allowed by the run's
modelPolicybanlist. Default banlist rejects haiku/mini/nano/lite/prior-gen (weak models produce noisy campaigns); sayany modelat init to turn the banlist off for that run. One no-improvement run is never "perfect".Promotion gate — promotion requires a tool-measured, deep-reverified result that moves the quality/cost frontier past threshold. Otherwise:
BLOCKED.
Two surfaces share one engine: the reactive MCP (a host calls its tools — the in-conversation hook) and the autonomous driver (super-loop-run CLI / run_campaign tool) that drives the whole campaign itself and only stops on the operator stop-file. The whole point: a model cannot promote, upgrade, or call a loop "perfect" from reasoning alone — every decision is hooked through a tool that demands tool-measured artifacts on disk, and the operator is the only stop condition.
Built fresh, zero dependencies, runs on plain Node ≥18. The full private 345-line Strip Miner and the full private 75-line Loop-de-loop (Loop 2) live inside the supervisor, byte-identical to source and hash-locked, streamed one section at a time.
The bundled loops (hash-locked)
| id | file | lines | sha256 | trigger |
|---|---|---|---|---|
strip-miner |
loops/strip-miner.txt |
345 | 5270d691…ed9ec9 |
/loop strip-miner (The Strip Miner Loop / cross-agent source miner) |
loop-de-loop |
loops/loop-de-loop.md |
75 | 70090e03…022b44 |
/loop loop-de-loop (Loop 2 / improve an approved loop) |
These are the local big sources — the operator's full private cross-agent Strip Miner (with the old pause/complete language patched into checkpoint/continue semantics), not the short public miner. The server refuses to start, and the test suite fails, if either file's hash or line count drifts — so the short public miner can never be silently substituted.
Add your own loops (local loop library)
Users add their own loops through a tool, not by hand-editing source:
loop_register { id:"my-loop", title:"My Loop", content:"<full loop text>" }   → hash-locked, sectionized, persisted locally
loop_library                                                                   → lists mandated (hash-locked) + your custom loops
loop_start  { loop:"my-loop" }                                                 → streams it phase-gated, exactly like the mandated loops
Custom loops are sha256 hash-locked (write-once per version; overwrite:true makes a new version), get a safe id (no path traversal), persist under SUPER_LOOP_HOME/custom-loops/, and cannot collide with or overwrite the mandated Strip Miner / Loop-de-loop. They stream through the same phase gate. Nothing leaves your machine.
Tools (29)
| tool | what it enforces |
|---|---|
run_campaign |
autonomous supervisor (opt-in SUPER_LOOP_ALLOW_EXEC=1) — drives the mine→improve queue, validates every worker, measures/reverifies challengers, and keeps review nonblocking. Each changed work epoch gets at most one empty mining pass: empty or duplicate output returns idle-no-new-work (NOT completion) instead of repeating paid calls. The standalone CLI stays alive in zero-inference idle and resumes from its target inbox. maxBatches is a safety cap, not completion. |
initialize_loop_run |
ask-once (brief + a few short Qs: goal, path picker (improve / discover / mine + library scout), the loop/domain, corpus scope + order, what "better" means, a hard limit, which models (enter = defaults, any model = banlist off), deeper-explanation; promotion mode / standing guarantees stay tool-owned); persists state.config.modelPolicy; stores every user message with a sha256 hash; surfaces the stop-condition notice, the cold-start notice (fresh run), and the native-continuation notice (Claude/Codex /goal; /loop = Claude's polling alternate) up front; returns a host-aware hostSetup with a path-aware step 3; honors the "deeper explanation" answer in the same response |
loop_register |
add your own loop to the local MCP: hash-lock, safe id, sectionize, persist locally; never overwrites a mandated loop |
loop_library |
list mandated (hash-locked) + custom local loops |
skill_fetch |
retrieve skill knowledge for the current task — plan mode returns an index of matching skills (titles, purposes, token estimates) to pick from; section mode fetches one section body by (skill_id, section_id); default partition working, reference is opt-in/held-out only |
loop_start |
begin phase-gated streaming of any loop (mandated or custom); returns section 0 only |
request_next_phase / loop_next |
next section iff the current one has evidence, else PHASE_SKIP |
observation_record |
lightweight phase evidence |
artifact_record |
persist a raw artifact + sha256; role:"baseline" hash-locks (write-once); measurement makes the MCP derive a tool-computed measurement from the bytes; pass explicit content (sourcePath reads refused) |
benchmark_propose / benchmark_select |
propose scorecards (≥1 value dim, ≥1 cost dim, ≥1 case, optional deterministic oracle) and freeze one; worker proposals carry benchSource:"worker" (default) and benchPartition:"harvest" |
benchmark_freeze_maker |
bench-maker only — freeze a scorecard directly with benchSource:"maker" (bypasses worker benchmark_propose); defaults benchPartition:"gate" for held-out eval |
export_trajectories |
read-only export of recorded tool actions as Hermes JSONL with supervisor verdict labels; refuses gate-partition runs |
benchmark_run |
set the tool-computed baseline bar; a caller-reported measurement is rejected |
register_hypotheses |
Standard mode: 3–5 hypotheses. Strict real-test mode: exactly two substantive, supervisor-ID-bound hypotheses for one finding. Benchmark-first; rejects banned routes and shape-only placeholders. |
test_hypothesis |
one full test = 3–5 frontier agents, each tool-computed; aggregates vs the bar; reports quality authority |
execute_full_test |
opt-in (SUPER_LOOP_ALLOW_EXEC=1) — the supervisor itself launches 3–5 allowlisted workers (native executables use direct shell-free execFile; allowlisted Windows .cmd/.bat shims use a narrow cmd.exe adapter; prompt always travels via stdin), captures output, parses real token usage, and gates on the tool-captured bytes; off by default → EXEC_DISABLED |
reverify_run |
re-derive metrics from the sealed raw bytes and confirm they reproduce (a tampered number cannot survive) |
promotion_request |
promote only on measured + reverified frontier movement; a quality win the MCP can't tool-verify routes to the dashboard (QUALITY_UNVERIFIED) |
cycle_decision_request |
the supervisor hook — a worker proposes a transition packet (promote/advance_phase/change_baseline/change_benchmark/saturate); only a supervisor-accepted transition is progress; completion/stop intents refused |
report_saturation |
mark a lane saturated → supervisor auto-transitions to the next lane (Strip Miner → Loop-de-loop); never pauses/stops |
campaign_status |
read-only lane/target queue, auto-transitions, 30-batch retirement + 10–15 advisory accounting, active modelPolicy, pending dashboard review (never blocks) |
continue_run |
records the next lane + first concrete action; it does not clear the obligation until a real progress tool runs |
human_review_request |
queue/list Approve/Sludge items only; model-callable resolve is blocked |
update_dashboard |
render the polished always-on local dashboard with the stop-condition notice |
report_export |
reproducible markdown campaign report |
host_capability_preflight |
local report of which frontier-agent CLIs are installed on PATH (filesystem stat only, never executes, not SOTA/web research) plus the resolved host profile — driverFamily, tier, setupHint, and the full host matrix when SUPER_LOOP_HOST is unknown |
host_runtime_detect |
advisory guess of which host runtime the agent is in, from which MCP config files exist on disk (per the host registry); read-only existence check — never reads file contents or mutates config; SUPER_LOOP_HOST is authoritative when set |
Block codes you will see
All 42 codes from src/constants.mjs BLOCK (runtime vocabulary):
NOT_INITIALIZED · UNKNOWN_RUN · NO_ACTIVE_LOOP · NOT_STARTED · PHASE_SKIP · UNKNOWN_LOOP · BASELINE_FIRST · BASELINE_LOCKED · BASELINE_BAR_FIRST · BASELINE_PLACEHOLDER · BASELINE_TOO_SHALLOW · BASELINE_AUTHOR_FORBIDDEN · BENCHMARK_FIRST · BENCHMARK_FROZEN · WEAK_BENCHMARK · HYPOTHESIS_COUNT · BANNED_ROUTE · UNKNOWN_HYPOTHESIS · FULLTEST_AGENTS · MODEL_REPORTED · NO_SCORE_MATRIX · NOT_REVERIFIED · BELOW_THRESHOLD · BELOW_FLOOR · STAGED_TRADEOFF · OPERATOR_IS_STOP · DASHBOARD_ONLY · MEASUREMENT_AUTHORITY · QUALITY_UNVERIFIED · PROMOTION_NEEDS_APPROVAL · PROMOTION_REJECTED · LOOP_EXISTS · LOOP_SOURCE · NO_ACTIVE_LANE (reserved — not currently emitted) · BUILDER_ROUTE · EXEC_DISABLED · EXEC_FAILED · ROUTE_UNSPAWNABLE · MANUAL_PROVENANCE_REQUIRED · INTEGRITY_GATE · TARGET_SATURATED_NEEDS_NEW_TARGET · BAD_INPUT
Live execution + autonomous harness (opt-in)
By default the server never executes commands (audited posture). Set SUPER_LOOP_ALLOW_EXEC=1 to let Loop Factory own benchmark execution end-to-end. Native executables stay on direct, shell-free execFile semantics. An allowlisted Windows .cmd or .bat npm shim alone goes through the dedicated cmd.exe adapter; % expansion syntax is refused before launch. The prompt remains stdin data and never reaches argv or the command string. On a Windows shim timeout, Loop Factory kills the ordinary descendant process tree before returning TIMEOUT; unconfirmed cleanup fails closed. A failed/timed-out/non-allowlisted launch is an invalid batch and does not count toward retirement.
The autonomous driver sits on top of that — the difference between "a supervisor you call" and "a harness that drives itself":
SUPER_LOOP_ALLOW_EXEC=1 node scripts/run-campaign.mjs --config campaign.json --stop-file ./STOP
It runs the whole loop unattended (intake → mine → improve targets → validate every worker → bank Stones → advance/retire → re-mine) and only stops when you create the stop-file. Existing queued targets continue even when reviews are pending. When a mining pass yields no novel candidate, the CLI enters a zero-inference idle state: the dashboard and decision inbox stay live, but no model is called again until new work arrives.
Queue new work atomically at <home>/runs/<runId>/inbox-targets.json:
{
  "runId": "your-run-id",
  "targets": [
    {
      "kind": "improve",
      "loop": "loop-de-loop",
      "baselineContent": "<complete current procedure>"
    }
  ]
}
The raw inbox is SHA-256 recorded and archived as applied/rejected/invalid before execution. The same supervisor logic powers the bounded run_campaign MCP call; because an MCP call cannot remain parked forever, that surface returns the nonterminal idle checkpoint for its host to resume.
Workers run on the real CLIs via stdin (claude -p --output-format json, codex exec --json) — the prompt never touches argv (no injection), and the real answer text + token usage are extracted for benchmarking. Benchmark modes: oracle (deterministic → tool-measured, reverified, then queued for mandatory operator Approve — never self-ships) and judge (an independent judge on a trusted builder/gating route from the active modelPolicy — defaults Opus/GLM — scores baseline-vs-challenger real outputs under a rubric → subjective → queues to the dashboard, never auto-promotes; the challenger never scores itself).
Model policy (operator-chosen at init)
Ask-once includes one friendly model question. Press enter / say defaults for today's historical behavior; say any model to set banlist.mode: "off" for that run. The policy is persisted as state.config.modelPolicy and shown on the dashboard + report.
For the Build Week lane, pass modelPreset: "gpt-5.6-sol" to initialize_loop_run or say use the gpt-5.6 sol preset. The preset uses the exact gpt-5.6-sol model ID as the primary and first full-test route while preserving the existing Opus/GLM builder boundary and Opus judge route. See examples/model-policy-gpt-5.6.json.
| Field | Default | Notes |
|---|---|---|
primary |
gpt-5.6-sol |
Primary worker route |
testRoutes |
gpt-5.6-sol / claude-fable-5 / gpt-5.6-terra | Full-test agent routes |
builderRoutes |
claude-fable-5 / gpt-5.6-sol | Builds + in-loop gating |
judgeRoute |
claude-fable-5 |
Independent judge; fallback is policy.primary |
banlist.mode |
default |
default = 21-pattern banlist; strict = also reject unknown frontier; off = only empty routes rejected |
banlist.extraAllow / extraDeny |
[] |
Punch holes or add denials per run |
Why a default banlist? Weak / cheap models produce noisy campaigns that look "done" without real frontier movement. That is a default, not a cage — you can disable it per run.
Controlled GPT-5.6 Sol enforcement proof
With an authenticated Codex CLI, run:
SUPER_LOOP_ALLOW_EXEC=1 npm run proof:gpt56-sol -- \
  --model gpt-5.6-sol \
  --out proof/build-week/gpt56-sol-live
This launches three short, explicitly adversarial fixtures through the real codex exec -m gpt-5.6-sol --json path in read-only, ephemeral mode. The fixtures ask the worker to propose a phase skip, a self-reported metric, and self-promotion; Loop Factory must reject each proposal with the matching supervisor code. Evidence includes raw JSONL, prompt/output hashes, the exact model argv receipt, token usage when the CLI reports it, persisted verdict events, a dashboard, and a markdown report. These are controlled regression prompts, not claims of spontaneous model behavior. The command refuses to overwrite an existing evidence directory and never falls back to another model.
A full campaign, in order
initialize_loop_run            → brief + ask-once (a few Qs) → answer → INITIALIZED
loop_start strip-miner         → section 0
  observation_record (phase 0) → request_next_phase → section 1 → … (gated)
artifact_record role=baseline  → hash-locked
benchmark_propose → benchmark_select        → scorecard frozen
artifact_record measurement → benchmark_run arm=baseline   → bar set (tool-measured)
register_hypotheses (3–5 frontier)
test_hypothesis (3–5 agents, tool-measured) → MOVED_FRONTIER | NO_IMPROVEMENT
reverify_run → promotion_request            → PROMOTE | BLOCKED
update_dashboard / report_export            → checkpoint; lanes keep running
Two distinct thresholds, neither of which stops the campaign:
- Risk advisory (10–15, configurable): after ~12 consecutive valid no-improvement full tests the supervisor raises an economic-exhaustion risk advisory and opens dashboard review — it only reports risk, it does not stop.
- Branch retirement (30 valid batches): a branch retires only after 30 valid full real test batches (3–5 frontier workers each) with no qualifying improvement, then the supervisor auto-pivots to the next lane. Invalid / fake-metric / early-stopped / summary-only batches are blocked upstream and never count.
If the Strip Miner saturates, the supervisor auto-transitions (Strip Miner → Loop-de-loop, or the next improvement lane) via report_saturation — never a pause/await/stop. Checkpoint/report/dashboard/refused-terminal/saturation/retirement events persist a machine-readable continuation obligation until a real progress tool runs. continue_run records the model's next-lane commitment but deliberately cannot clear the obligation by itself. Only the operator stops the campaign.
Design notes
- Zero dependencies on purpose. No SDK, nothing to
npm installthat can fail or time out, nothing phoning home. The MCP transport is ~90 lines of newline-delimited JSON-RPC insrc/server.mjs. There is nothing to install. - Tool-computed measurement authority. The MCP derives quality from the frozen oracle and derives an internal deterministic estimate from recorded output bytes. User-facing reports label that estimate
artifactOutputTokenEstimate; executor receipts showcliReportedTotalTokensanddurationMsseparately. In strict mode each counted agent run directly links a raw stdout artifact and extracted final artifact whose SHA-256 values match the invocation receipt. A number the model types iscaller-reportedand is refused by the benchmark/test gates (MEASUREMENT_AUTHORITY).reverify_runre-derives from the sealed bytes, so a tampered number cannot survive. Subjective quality routes to the dashboard for a human and never auto-promotes (QUALITY_UNVERIFIED); deterministic, oracle-scored quality still queues for mandatory operator Approve before it becomes an internal champion. - Host capability preflight, no execution.
host_capability_preflightresolves known frontier-agent CLI names againstPATHwith a filesystem stat — it never spawns a command, never probes a model-supplied binary, and is not SOTA/web research. Presence on PATH ≠ working auth, and it says so. - Anti-tampering. Baseline and benchmark are write-once within a cycle; changing either needs an explicit new epoch + rationale.
- Path hardening.
runIdand artifact ids are validated before touching disk, andsourcePathreads are refused so a model cannot turn the MCP into a local-file reader. Submit artifact bytes throughcontent. - Dashboard-only human review, with a real apply path. The model-callable MCP surface can queue/list review items (and may propose a loop adoption carrying improved loop text), but
human_review_request { action:"resolve" }returnsDASHBOARD_ONLY. The served dashboard is the HTTP decision surface: choose Approve/Deny, then explicitly confirm the queue action. The local server binds to 127.0.0.1, requires a loopback Host, a same-origin browser request, a per-server session token, and the SHA-256 binding for the exact reviewed state. Queue acceptance remains visibly distinct from supervisor application, survives a reload, and the supervisor rejects a decision if its evidence binding changed before drain. Headless fallback exports the same hash-bound payload forruns/<runId>/inbox-decisions.jsonornode scripts/apply-decisions.mjs --file <export>. Approving a loop-adoption review installs the improved loop as a new versioned custom loop (the prior version is archived for rollback viaoperator.rollbackLoop), whichloop_startthen streams next cycle. The mandated canonical loops are immutable and never touched. Applying is non-blocking — the campaign never pauses for it, and adoption remains off the model-callabletools/callsurface. - Continuation is a host obligation, stated honestly. An MCP cannot force the host agent loop to keep running — only the host can (which is why the agent is told its native continuous command — Claude Code / Codex
/goal, with/loopas Claude's polling alternate, or the per-host driver from the registry — on start). What the MCP can do, and does: every report / dashboard / saturation / no-improvement / refused-terminal event persists a machine-readable continuation obligation with a concrete next tool+lane, andcontinue_runrecords intent without clearing it (only a real progress tool clears it). The MCP makes stopping early visibly incomplete; it does not pretend to be the host scheduler. The operator is the only stop condition. - Never overwrites your canonical loop. Promotion records an internal champion; changing the canonical loop file is HUMAN-GATED and left to you.
- Standalone by design.
Run-trajectory export
Bench-maker sessions are out-of-lineage: a separate operator-controlled MCP invocation freezes held-out scorecards; the worker being measured never proposes them.
Protocol (ephemeral bench-maker)
- Spin up a dedicated MCP host pointed at the same
SUPER_LOOP_HOME(or a copy) with a freshrunIdfor the held-out worker run. - Hash-lock baseline on that run:
artifact_record { role:"baseline", content:"..." }. - Freeze held-out benchmark via
benchmark_freeze_maker(notbenchmark_propose):
This sets{ "runId": "<eval-run>", "benchmark": { "name": "...", "taskValueDimensions": ["..."], "resourceDimensions": ["..."], "cases": [{ "id": "..." }], "oracle": "..." }, "benchPartition": "gate" }benchSource:"maker"andbenchPartition:"gate". Workerbenchmark_proposeon that run becomes a no-op while the maker scorecard is frozen. - Run the worker through the normal phase gate / hypotheses / full tests on the gate benchmark.
- Do not export gate runs for reuse —
export_trajectoriesrefusesbenchPartition:"gate"runs (hard firewall against exam-set leakage). - Harvest runs (worker-frozen benchmarks with default
benchPartition:"harvest") export via:
Output is Hermes-format JSONL: one line per recorded tool call with{ "runId": "<harvest-run>", "outPath": "trajectory.jsonl" }label.verdict/label.code/label.reasonfrom the sealed gate results already stored on the run (never re-run gates). - Terminate the bench-maker host session when done — no persistent bench-maker process is required; access is operational (separate host invocation), not a background daemon.
Layout
loops/            bundled hash-locked loop sources (verified once per process, then cached)
hosts/            host runtime registry (PURE DATA — continuous drivers + tiers)
examples/         campaign configs, improve-driver, MCP host snippets, rules
src/
  server.mjs      MCP stdio JSON-RPC transport + tool schemas
  engine.mjs      Loop Factory core — every tool handler + gate
  integrity.mjs   Integrity Gate — negative control, answer-key/padded echo, solution pressure
  loops.mjs       registry, hash verify-on-first-load + process cache, sectionizer
  measure.mjs     tool-computed measurement (derive cost/quality from bytes) + honest boundary
  executor.mjs    opt-in live worker execution (allowlist, execFile, stdin) — off by default
  run-verifier.mjs independent read-only receipt/artifact publication verifier
  canary-runner.mjs blinded one-proposal / three-arm executable canary
  schemas/        strict Codex final-output JSON schemas
  supervisor.mjs  autonomous campaign driver (validate → accept/re-enter boundary)
  host.mjs        host capability preflight + registry loader
  models.mjs      modelPolicy / banlist (operator-chosen at init; defaults = historical)
  scorecard.mjs   promotion frontier rule + score matrix
  skill-schema.mjs skill frontmatter + section schema (shared frontmatter parser)
  skill-match.mjs  skill ranking / match against task
  store.mjs       local atomic JSON persistence (runs + custom-loops + skills)
  dashboard.mjs   polished dashboard.html + markdown report
  constants/util  shared facts + helpers
scripts/          demo.mjs, run-campaign.mjs, run-real-test-canary.mjs, verify-run.mjs,
                  dashboard-server.mjs, apply-decisions.mjs,
                  verify-sources.mjs, flywheel-harden.mjs, quarantine-addendum.mjs,
                  tier-test.mjs, trajectory-capture.mjs, verify-trajectory.mjs
test/             node:test suites (sources, ask-once, phase gate, benchmark,
                  hypotheses, promotion, hook, dashboard, transport, security,
                  loop library, measurement authority, host preflight, executor,
                  supervisor, adoption, dashboard-server)
License
MIT
Установка Super Loop
У этого сервера нет опубликованного пакета — он собирается из исходников. Открой репозиторий и следуй инструкции в README.
▸ github.com/alexalexalex222/Loop-Factory-mcp-publicFAQ
Super Loop MCP бесплатный?
Да, Super Loop MCP бесплатный — установка в пару кликов через Unyly без оплаты.
Нужен ли API-ключ для Super Loop?
Нет, Super Loop работает без API-ключей и переменных окружения.
Super Loop — hosted или self-hosted?
Self-hosted: сервер запускается локально на твоей машине командой из раздела установки.
Как установить Super Loop в Claude Desktop, Claude Code или Cursor?
Открой Super Loop на unyly.org, выбери вкладку своего клиента (Claude Desktop, Claude Code, Cursor) и нажми Install — конфиг сгенерируется автоматически, без правки JSON.
Похожие MCP
Fetch
Web content fetching and conversion for efficient LLM usage.
Roblox Studio
Enables AI coding tools to control Roblox Studio for workspace exploration, instance manipulation, and script management. It provides tools for playtesting, sce
 автор: paralov
Opencode Omniroute Plugin
OpenCode plugin for the OmniRoute AI Gateway. Drives dynamic model discovery, /connect auth flow, and multi-instance OmniRoute providers via the official @openc
 автор: GitHub Actions
AWS KB Retrieval
Retrieval from AWS Knowledge Base using Bedrock Agent Runtime.
 автор: modelcontextprotocol
Spring AI MCP Server
Provides auto-configuration for setting up an MCP server in Spring Boot applications.
llm-analysis-assistant
A very streamlined mcp client that supports calling and monitoring stdio/sse/streamableHttp, and can also view request responses through the /logs page. It also
 автор: xuzexin-hz
MCP-Agent
A simple, composable framework to build agents using Model Context Protocol by [LastMile AI](https://www.lastmileai.dev)
 автор: lastmile-ai
Spring AI MCP Client
Provides auto-configuration for MCP client functionality in Spring Boot applications.
mcp.natoma.ai
A Hosted MCP Platform to discover, install, manage and deploy MCP servers by [Natoma Labs](https://www.natoma.ai)
MCPHub
Website to list high quality MCP servers and reviews by real users. Also provide online chatbot for popular LLM models with MCP server support.
Compare Super Loop with
Не уверен что выбрать?
Найди свой стек за 60 секунд
Автор?
Embed-бейдж для README
Похожее
Все в категории ai