
elhamid/llm-council
БесплатноНе проверенMulti-LLM deliberation with anonymized peer review: parallel responses, anonymous ranking and synthesis, based on Andrej Karpathy's LLM Council concept.

Описание
Multi-LLM deliberation with anonymized peer review: parallel responses, anonymous ranking and synthesis, based on Andrej Karpathy's LLM Council concept.
README
Fork notes (elhamid)
This is a fork of karpathy/llm-council.
Update — 2025-12-19 (Stability + auditability pass)
New in this fork since the previously published state:
- Conversation history is complete again: storage loads older runs from
backend/data/conversations.jsonand supports the legacydata/layout (includingdata/conversations/per-conversation JSON files when present), so older runs show up in the UI. - Sidebar no longer truncates early: the frontend now requests
/api/conversations?limit=500so the conversation list reliably shows full history. - Stage 2 judge duplication fixed: Stage 2 now dedupes judge models so evaluation does not silently double-count the same judge.
- Titles persist correctly: after Stage 3 completes, a title is derived and saved to the conversation record, so it sticks across refreshes and appears in history.
- Tooling + reproducibility: added Stage 2 smoke/quality scripts and supporting evaluation artifacts to make regressions repeatable.
- Roles updated + clarified: earlier fork notes described roles as Analyst / Researcher / Critic / Provocateur; the implemented role set is now Builder / Reviewer / Synthesizer / Contrarian (with a provider-default mapping in
backend/roles.py). This keeps the “multi-perspective” intent, but with clearer, more actionable role behavior.
Value added — 2025-12-14 (decision-quality focused)
- Decision-auditable runs: every council response is saved with a compact decision trace (Stage 1 answers, Stage 2 rankings, and the Stage 2→model mapping), so you can inspect why the Chairman concluded what it did — not just the final text.
- Reduced “model-brand” bias in judging: Stage 2 rankings operate on anonymized responses (Response A/B/C/…), and the label→model mapping is preserved for post-hoc review. This keeps peer review focused on content quality rather than model identity.
- Role-separated council behavior: explicit role specs (Analyst / Researcher / Critic / Provocateur + Chairman) make the council behave more like a real review board: one pushes rigor, one hunts missing facts, one stress-tests, one challenges assumptions — then the Chairman synthesizes.
- Repeatable scoring across runs: aggregated ranks (average rank + count) are persisted so you can compare council behavior over time and across prompts, instead of treating each run as a one-off chat.
Implementation notes (supporting the above)
- Real SSE endpoint (
text/event-stream) for/api/conversations/{id}/message/streamwith incrementalstage*_start/completeevents. - Persist
meta/metadata(label_to_model,aggregate_rankings,model_roles) so Stage2 renders correctly and the run is reviewable later. - Frontend Stage2 reads
msg.meta || msg.metadataso fork/upstream payload shapes both render.
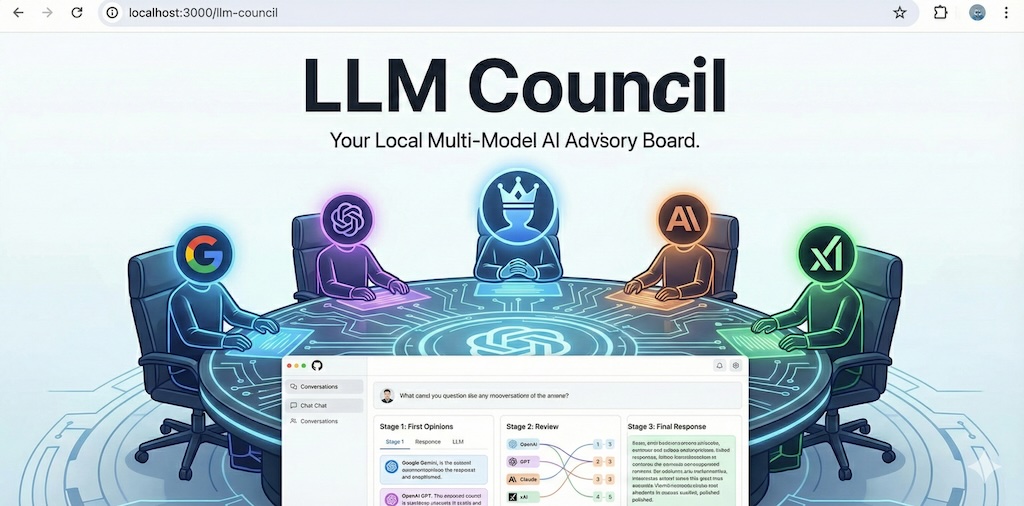
The idea of this repo is that instead of asking a question to your favorite LLM provider (e.g. OpenAI GPT 5.1, Google Gemini 3.0 Pro, Anthropic Claude Sonnet 4.5, xAI Grok 4, eg.c), you can group them into your "LLM Council". This repo is a simple, local web app that essentially looks like ChatGPT except it uses OpenRouter to send your query to multiple LLMs, it then asks them to review and rank each other's work, and finally a Chairman LLM produces the final response.
In a bit more detail, here is what happens when you submit a query:
- Stage 1: First opinions. The user query is given to all LLMs individually, and the responses are collected. The individual responses are shown in a "tab view", so that the user can inspect them all one by one.
- Stage 2: Review. Each individual LLM is given the responses of the other LLMs. Under the hood, the LLM identities are anonymized so that the LLM can't play favorites when judging their outputs. The LLM is asked to rank them in accuracy and insight.
- Stage 3: Final response. The designated Chairman of the LLM Council takes all of the model's responses and compiles them into a single final answer that is presented to the user.
Vibe Code Alert
This project was 99% vibe coded as a fun Saturday hack because I wanted to explore and evaluate a number of LLMs side by side in the process of reading books together with LLMs. It's nice and useful to see multiple responses side by side, and also the cross-opinions of all LLMs on each other's outputs. I'm not going to support it in any way, it's provided here as is for other people's inspiration and I don't intend to improve it. Code is ephemeral now and libraries are over, ask your LLM to change it in whatever way you like.
Setup
1. Install Dependencies
The project uses uv for project management.
Backend:
uv sync
Frontend:
cd frontend
npm install
cd ..
2. Configure API Key
Create a .env file in the project root:
OPENROUTER_API_KEY=sk-or-v1-...
Get your API key at openrouter.ai. Make sure to purchase the credits you need, or sign up for automatic top up.
3. Configure Models (Optional)
Edit backend/config.py to customize the council:
COUNCIL_MODELS = [
    "openai/gpt-5.1",
    "google/gemini-3-pro-preview",
    "anthropic/claude-sonnet-4.5",
    "x-ai/grok-4",
]

CHAIRMAN_MODEL = "google/gemini-3-pro-preview"
Running the Application
Option 1: Use the start script
./start.sh
Option 2: Run manually
Terminal 1 (Backend):
uv run python -m backend.main
Terminal 2 (Frontend):
cd frontend
npm run dev
Then open http://localhost:5173 in your browser.
Tech Stack
- Backend: FastAPI (Python 3.10+), async httpx, OpenRouter API
- Frontend: React + Vite, react-markdown for rendering
- Storage: JSON files in
data/conversations/ - Package Management: uv for Python, npm for JavaScript
Установка elhamid/llm-council
У этого сервера нет опубликованного пакета — он собирается из исходников. Открой репозиторий и следуй инструкции в README.
▸ github.com/elhamid/llm-councilFAQ
elhamid/llm-council MCP бесплатный?
Да, elhamid/llm-council MCP бесплатный — установка в пару кликов через Unyly без оплаты.
Нужен ли API-ключ для elhamid/llm-council?
Нет, elhamid/llm-council работает без API-ключей и переменных окружения.
elhamid/llm-council — hosted или self-hosted?
Self-hosted: сервер запускается локально на твоей машине командой из раздела установки.
Как установить elhamid/llm-council в Claude Desktop, Claude Code или Cursor?
Открой elhamid/llm-council на unyly.org, выбери вкладку своего клиента (Claude Desktop, Claude Code, Cursor) и нажми Install — конфиг сгенерируется автоматически, без правки JSON.
Похожие MCP
Opencode Omniroute Plugin
OpenCode plugin for the OmniRoute AI Gateway. Drives dynamic model discovery, /connect auth flow, and multi-instance OmniRoute providers via the official @openc
 автор: GitHub Actions
Roblox Studio
Enables AI coding tools to control Roblox Studio for workspace exploration, instance manipulation, and script management. It provides tools for playtesting, sce
 автор: paralov
Antigravity Drawio
MCP server that enables AI assistants to create, parse, render, and validate Draw.io diagrams programmatically.
 автор: S-SUJAN-S
Fetch
Web content fetching and conversion for efficient LLM usage.
AWS KB Retrieval
Retrieval from AWS Knowledge Base using Bedrock Agent Runtime.
 автор: modelcontextprotocol
Spring AI MCP Server
Provides auto-configuration for setting up an MCP server in Spring Boot applications.
llm-analysis-assistant
A very streamlined mcp client that supports calling and monitoring stdio/sse/streamableHttp, and can also view request responses through the /logs page. It also
 автор: xuzexin-hz
MCP-Agent
A simple, composable framework to build agents using Model Context Protocol by [LastMile AI](https://www.lastmileai.dev)
 автор: lastmile-ai
Spring AI MCP Client
Provides auto-configuration for MCP client functionality in Spring Boot applications.
mcp.natoma.ai
A Hosted MCP Platform to discover, install, manage and deploy MCP servers by [Natoma Labs](https://www.natoma.ai)
Compare elhamid/llm-council with
Не уверен что выбрать?
Найди свой стек за 60 секунд
Автор?
Embed-бейдж для README
Похожее
Все в категории ai