
Hkex Filing Scraper
БесплатноНе проверенScrape 25+ years of HKEx (Hong Kong Stock Exchange) regulatory filings into PostgreSQL, MySQL/MariaDB, SQLite, MongoDB, Neo4j, ClickHouse, DuckDB, or SurrealDB

Описание
Scrape 25+ years of HKEx (Hong Kong Stock Exchange) regulatory filings into PostgreSQL, MySQL/MariaDB, SQLite, MongoDB, Neo4j, ClickHouse, DuckDB, or SurrealDB — with full-text extraction, graph linking, and a hosted MCP server for AI agents.
README
CI GitHub Release PyPI License: MIT Python 3.10+ MCP Docs Ruff PRs Welcome
PostgreSQL MySQL SQLite MongoDB Neo4j ClickHouse DuckDB SurrealDB
An open-source Python tool that scrapes 25+ years of Hong Kong Stock Exchange (HKEx) regulatory filings and ingests them into any combination of nine databases — with full-text and table extraction, chunk-level coverage, optional graph linking, and a read-only MCP server so AI agents can query the corpus or the live site.
It speaks the undocumented HKEx JSON API directly, which is faster and more resilient than driving a browser.
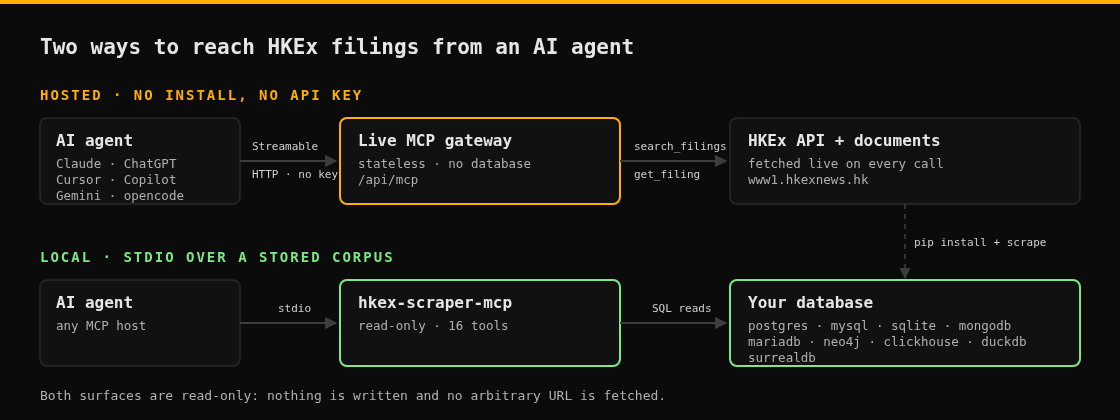
Two ways to use it
| Hosted MCP gateway | Local pipeline | |
|---|---|---|
| What | A public endpoint you point an AI agent at | The hkex-scraper CLI |
| Setup | None — paste a URL | pip install + one environment variable |
| Data | Live from HKEx, nothing stored | Stored in your database(s) |
| Docs | Live MCP gateway · AI agent support | Getting started |
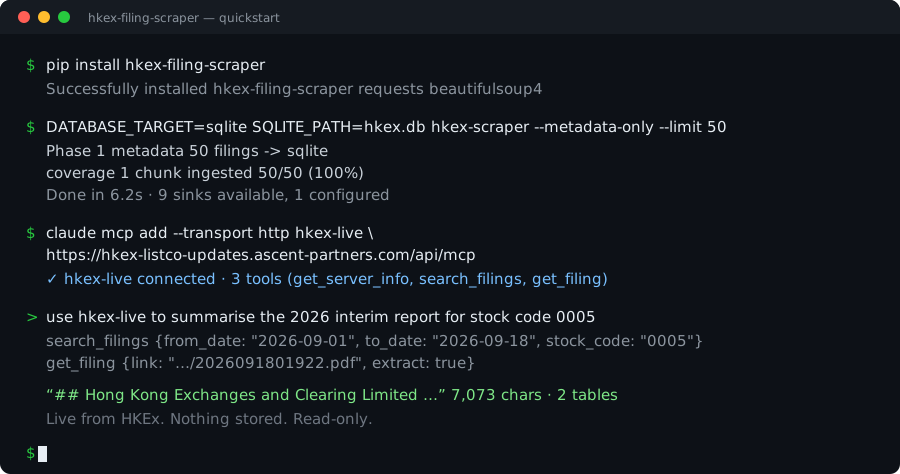
Use the hosted MCP gateway
POST, Streamable HTTP, no API key:
https://hkex-listco-updates.ascent-partners.com/api/mcp
Three read-only tools: get_server_info, search_filings (a window of at most 31 days), and
get_filing (downloads one document and extracts its text and tables).
Point a client at it — for example opencode:
{
  "$schema": "https://opencode.ai/config.json",
  "mcp": {
    "hkex-live": {
      "type": "remote",
      "url": "https://hkex-listco-updates.ascent-partners.com/api/mcp"
    }
  }
}
Then ask:
Use hkex-live to list the filings published between 2026-09-01 and 2026-09-18,
then summarise the interim report.
Ready-made configuration for Claude, ChatGPT, Cursor, VS Code/Copilot, Gemini CLI, opencode,
Manus, and Perplexity is in AI agent support — and for a stored corpus,
the stdio MCP server exposes a wider tool catalog. The gateway is listed in the
official MCP Registry as
io.github.simonplmak-cloud/hkex-filings.
Quick start (local)
pip install hkex-filing-scraper        # core; SQLite needs no server
pip install "hkex-filing-scraper[all]" # Excel + dotenv + every driver + the MCP server
cp .env.example .env                   # then set DATABASE_TARGET (below)
hkex-scraper --metadata-only --limit 100
Optional extras: excel, postgres, mysql, duckdb, mongodb, clickhouse, neo4j,
mcp, pdf, all, dev.
DATABASE_TARGET is an ordered, comma-separated list of sink ids; the order decides which
sink serves reads. To start with no server:
DATABASE_TARGET=sqlite
SQLITE_PATH=hkex.db
hkex-scraper runs the full pipeline (metadata + documents + graph); hkex-scraper --full-history covers everything since April 1999. The schema is created automatically.
Full install options and per-sink settings are in Getting started.
Database support
Every sink is a first-class destination; rows are in documented popularity order. The full matrix — licenses, capability differences, per-engine notes — is in Database sinks.
| Sink | Model | License | Extra | Idempotent upsert |
|---|---|---|---|---|
postgres |
relational | PostgreSQL License | postgres |
ON CONFLICT DO UPDATE |
mysql / mariadb |
relational | GPLv2 | mysql |
ON DUPLICATE KEY UPDATE |
sqlite |
relational | Public domain | — | ON CONFLICT DO UPDATE |
mongodb |
document | SSPL¹ | mongodb |
update_one(upsert=True) |
neo4j |
graph | GPLv3 (Community) | neo4j |
MERGE |
clickhouse |
columnar | Apache-2.0 | clickhouse |
ReplacingMergeTree + read-merge |
duckdb |
relational | MIT | duckdb |
ON CONFLICT DO UPDATE |
surrealdb |
graph + document | BSL 1.1¹ | — | UPSERT / RELATE |
¹ Source-available, not OSI-approved — labelled exceptions per ADR 0003.
Valid sink ids, in documented order: postgres, mysql, sqlite, mongodb, mariadb, neo4j, clickhouse, duckdb, surrealdb. Set one variable and the same run feeds every sink:
# Order sets read precedence.
DATABASE_TARGET=postgres,sqlite
POSTGRES_DSN=postgresql://user:password@localhost:5432/hkex
SQLITE_PATH=hkex.db
How it works
flowchart LR
    A[HKEx JSON API] --> B[Phase 1: metadata]
    B --> C[Canonical record]
    C --> D{DATABASE_TARGET}
    D --> E[(PostgreSQL)]
    D --> F[(MySQL / MariaDB)]
    D --> G[(SQLite)]
    D --> H[(MongoDB)]
    D --> I[(Neo4j)]
    D --> J[(ClickHouse)]
    D --> K[(DuckDB)]
    D --> L[(SurrealDB)]
    B --> M[Graph linking]
    M --> D
    B --> N[Phase 2: download and extract]
    N --> C
- Phase 1 scrapes filing metadata through a JSF session, splitting the range into monthly
chunks and deduplicating on a 16-character MD5
filingId. - Phase 2 downloads each filing's PDF/HTML/Excel document, extracts text and tables to Markdown, and writes the payload.
- Graph linking (optional) writes
has_filingandreferences_filingedges whenCOMPANY_TABLEis set. - Failure isolation — a failure on one sink is logged and counted but never blocks another; the run exits non-zero if any configured sink failed.
Deeper detail: Architecture · ADR 0002.
Features
- Fast API scraping — direct HKEx JSON API; no browser or Selenium.
- Full history — every filing from April 1999 to today, with chunk-level coverage checks.
- Document processing — PDF/HTML/Excel text and structured tables, extracted to Markdown.
- Multi-sink — any ordered combination of nine databases, each with native idempotent upserts.
- AI-ready — a hosted live MCP gateway plus a local stdio MCP server.
- Resumable and observable — batching, parallel downloads, stalled-job detection, per-sink
counters, and
--coverage-report/--parity-report/--verify. - Optional dependencies — the core is
requests+beautifulsoup4; drivers and document extraction are extras with graceful fallbacks.
Documentation
- Getting started · Configuration · CLI
- Database sinks (matrix) — PostgreSQL, MySQL/MariaDB, SQLite, MongoDB, Neo4j, ClickHouse, DuckDB, SurrealDB
- Live MCP gateway · AI agent support · MCP server
- Architecture · Troubleshooting · Testing
- Roadmap · De-risking register · Upgrading
- What's new · Releasing · Legal & Terms of Use · Changelog
- Docs site: https://hkex-listco-updates.ascent-partners.com/ · Try it locally (examples/)
Development
pip install -e ".[dev,all]"
ruff check           # lint (py310, line-length 100)
ruff format --check  # formatting
pytest               # unit tests (no DB or network required)
Tests are pure unit tests; SQLite and DuckDB contract tests run in-process, and integration tests that need a server are skipped unless that sink is configured. See Testing.
Contributing
See CONTRIBUTING.md; report security issues per SECURITY.md. Ideas and questions are welcome in Discussions.
If this saves you time, a star helps others find it.
License
MIT — see LICENSE. That covers this project's code only; optional dependencies
carry their own licenses, notably the pdf extra (PyMuPDF / pymupdf4llm), which is
AGPL-3.0 and deliberately excluded from .[all]. See
docs/legal.md.
Data & Terms of Use: this is a research tool for the undocumented HKEx JSON API, and it is not affiliated with or endorsed by HKEx. Commercial redistribution of HKEx data may require a licensed HKEx feed; see docs/legal.md.
Установить Hkex Filing Scraper в Claude Desktop, Claude Code, Cursor
unyly install hkex-filing-scraperСтавит в Claude Desktop, Claude Code, Cursor и VS Code — сам разбирается с npx, uvx и сборкой из исходников.
Впервые? Поставь CLI: curl -fsSL https://unyly.org/install | sh
Или настроить вручную
Выполни в терминале:
claude mcp add hkex-filing-scraper -- uvx hkex-filing-scraperПошаговые гайды: как установить Hkex Filing Scraper
FAQ
Hkex Filing Scraper MCP бесплатный?
Да, Hkex Filing Scraper MCP бесплатный — установка в пару кликов через Unyly без оплаты.
Нужен ли API-ключ для Hkex Filing Scraper?
Нет, Hkex Filing Scraper работает без API-ключей и переменных окружения.
Hkex Filing Scraper — hosted или self-hosted?
Self-hosted: сервер запускается локально на твоей машине командой из раздела установки.
Как установить Hkex Filing Scraper в Claude Desktop, Claude Code или Cursor?
Открой Hkex Filing Scraper на unyly.org, выбери вкладку своего клиента (Claude Desktop, Claude Code, Cursor) и нажми Install — конфиг сгенерируется автоматически, без правки JSON.
Похожие MCP
wenb1n-dev/SmartDB_MCP
A universal database MCP server supporting simultaneous connections to multiple databases. It provides tools for database operations, health analysis, SQL optim
 автор: wenb1n-dev
Postgres Server
This server enables interaction with PostgreSQL databases through the Model Context Protocol, optimized for the AWS Bedrock AgentCore Runtime. It provides tools
 автор: madhurprash
Postgres
Query your database in natural language
 автор: Anthropic
PostgreSQL
Read-only database access with schema inspection.
автор: modelcontextprotocolRedis
Interact with Redis key-value stores.
автор: modelcontextprotocolSQLite
Database interaction and business intelligence capabilities.
автор: modelcontextprotocolmxcp
Open-source framework for building enterprise-grade MCP servers using just YAML, SQL, and Python, with built-in auth, monitoring, ETL and policy enforcement.
 автор: raw-labs
tadas-github/a2asearch-mcp
MCP server to search 4,800+ MCP servers, AI agents, CLI tools and agent skills. Install: npx -y a2asearch-mcp. Ask Claude: "Find MCP servers for database access
 автор: tadas-github
julien040/anyquery
Query more than 40 apps with one binary using SQL. It can also connect to your PostgreSQL, MySQL, or SQLite compatible database. Local-first and private by desi
 автор: julien040
drakonkat/wizzy-mcp-tmdb
A MCP server for The Movie Database API that enables AI assistants to search and retrieve movie, TV show, and person information.
 автор: drakonkat
Compare Hkex Filing Scraper with
Не уверен что выбрать?
Найди свой стек за 60 секунд
Автор?
Embed-бейдж для README
Похожее
Все в категории data