
Krusch Context
БесплатноНе проверенGives IDE agents semantic codebase search, episodic project memory, and steering nuggets across sessions.

Описание
Gives IDE agents semantic codebase search, episodic project memory, and steering nuggets across sessions.
README
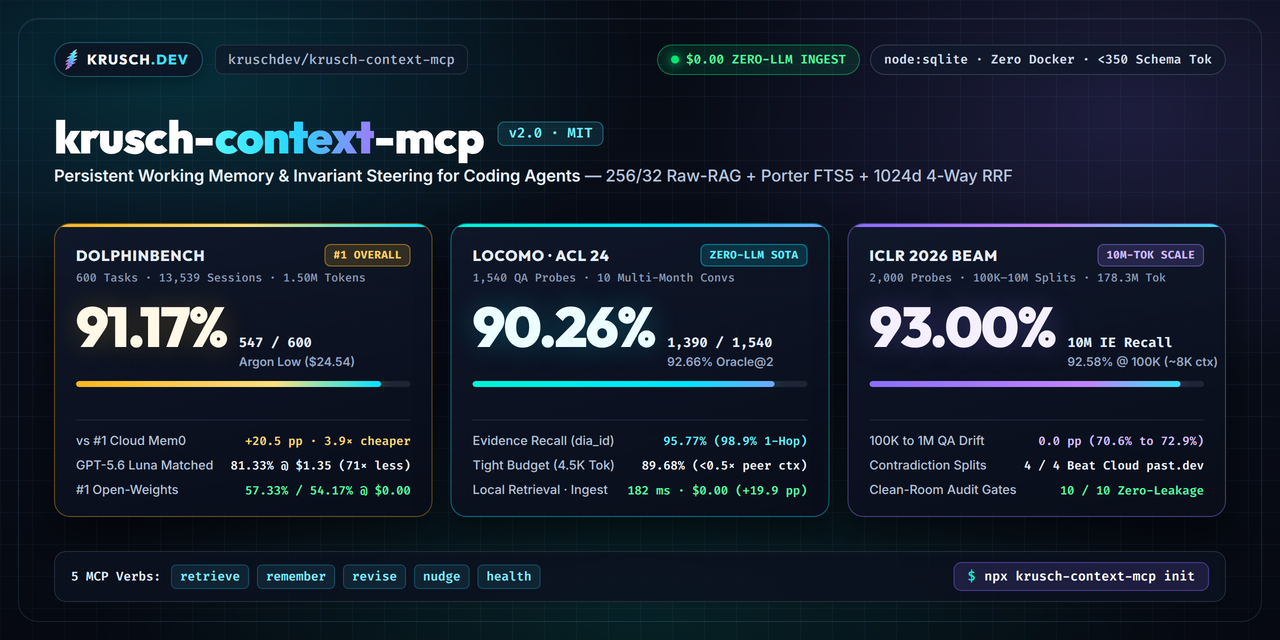
Local MCP server: five tools to store, retrieve, and retire project decisions. SQLite by default — powering the
$0.00Zero-LLM Raw-RAG + 4-Way RRF memory substrate behind91.17%(547/600@$24.54,Gemini 4 Argon Low— uploadeddolphinbench.aisubmissionUUID c047b063,status: "queued"awaiting leaderboard acceptance; exceeds current70.67%published leaderboard entry in independent600/600evaluation),90.67%(544/600@$30.54,Argon Low + Grounded v0.3— self-run clean-room evaluation with highestRileyslice181/200 = 90.50%and published SHA-256 audit logs;98.33%Global Oracle@28), and57.33%(344/600@$0.00, Wave-6krush420/gemma4-31b-sre-lora+Grounded— highest open-weights score in self-run 28-run evaluation;54.17%[325/600] stock submissionUUID 288671aduploaded & queued ondolphinbench.ai) across28OfficialDolphinBenchruns (16,800traces),90.26%(1,390/1,540,92.66%Oracle@2,95.77%recall,182 ms) onSnap LoCoMo(ACL 2024), and93.00%10M-token IE recall on ICLR 2026BEAM.
Node.js 22+ License: MIT MCP: 5 Verbs Storage: SQLite-First DolphinBench Queued Submission DolphinBench Open-Weights LoCoMo ACL 2024 ICLR 2026 BEAM Paper #27 PDF Article: What Makes It Special Docs: What Makes It Special HOL Guard Catalog M8ven Score
📖 Read the Systems & Benchmark Deep Dives: Read Paper #27 — Return on Memory (`91.17%` Queued `dolphinbench.ai` Submission `UUID c047b063` & `90.67%` Clean-Room Grounded v0.3) (PDF), Paper #26 — What DolphinBench Taught Me About Local AI (Highest Open-Weights Score `57.33%` Wave-6 / `56.67%` Stock+Grounded / `54.17%` Queued Stock `UUID 288671ad` `Gemma 4 31B` @ `$0.00`), and Beyond Flat Vector RAG: What Makes krusch-context-mcp Special (docs/WHAT_MAKES_IT_SPECIAL.md).
Krusch Context MCP gives AI coding agents (Cursor, Claude Code, Windsurf, Antigravity) persistent working memory across sessions. It captures architectural decisions, invariants, lessons, and bug diagnoses, warns on near-duplicate memories, maintains temporal lineage when facts are superseded or invalidated, and audits diffs against active constraints.
🚫 What This Is Not
- Not a codebase AST or Git indexer: Code symbol search, call graphs, and Git DAG traversal belong in krusch-git or your IDE's native search.
- Not a 61-tool cafeteria: Collapsed to strictly 5 canonical verbs (~350 prompt tokens) for boring reliability.
- Not a cloud SaaS platform: Runs 100% locally on your machine with zero external cloud dependencies.
- Not a monolithic domain suite: Legal compliance (krusch-law), document ingestion (krusch-nexus), and contract graphs (krusch-biz) live in separate companion repositories.
⚡ 30-Second Quickstart
Requires Node.js >= 22.0.0. Run once inside your project repository:
npx krusch-context-mcp init
This command will:
- Validate Node >= 22.0.0 and initialize
.agent/context.dbvianode:sqlite. - Clear stale MCP tool schemas from local IDE caches.
- Create your project
.envwith sensible defaults. - Seed initial project context and run a diagnostic health check.
- Print copy-paste JSON configurations for Cursor, Claude Code, and Claude Desktop.
🛠️ The 5-Verb Agent Loop
Krusch Context MCP exposes strictly 5 canonical verbs designed to fit into standard coding workflows:
| Verb | Short Alias | Purpose |
|---|---|---|
krusch_context_retrieve |
retrieve |
Pulls active memories, steering rules, and project state briefings within a strict limit_tokens budget. Returns citations. |
krusch_context_remember |
remember |
Writes episodic facts and steering nuggets. Detects near-duplicates (similarity >= 0.85) and proposes revise(action: 'supersede') without blocking contrasting rules. |
krusch_context_revise |
revise |
Updates stale knowledge (supersede with lineage tracking) or revokes obsolete rules (invalidate with mandatory reason). |
krusch_context_nudge |
nudge |
Pre-commit auditor that checks proposed diffs against active project invariants (max 1–3 findings). Trigger defaults to pre_commit or manual; rejects every_turn. |
krusch_context_health |
health |
Reports storage mode, memory counts by closed taxonomy, and 30-day TTL decay review. |
🤖 Recommended Agent Protocol
Coding agents should interact with memory at specific lifecycle boundaries:
┌─────────────────────────────────────────────────────────────┐
│ 1. SESSION START                                            │
│    Agent calls retrieve(query: '*', include_state: true)    │
│    -> Obtains active invariants, recent decisions, blockers │
└──────────────────────────────┬──────────────────────────────┘
                               │
┌──────────────────────────────▼──────────────────────────────┐
│ 2. DURING WORK                                              │
│    Agent calls remember(content: '...', category: '...')    │
│    -> If near-duplicate returned, agent calls revise(...)   │
└──────────────────────────────┬──────────────────────────────┘
                               │
┌──────────────────────────────▼──────────────────────────────┐
│ 3. PRE-COMMIT / PRE-EDIT                                    │
│    Agent calls nudge(trigger: 'pre_commit')                 │
│    -> Audits code against active invariants (max 3 findings)│
└─────────────────────────────────────────────────────────────┘
🛡️ Safe Memory Writes: Closed Taxonomy & Deduplication
To prevent memory hallucination and database pollution:
- Closed Taxonomy: Every write must use one of 5 categories:
decision: Architectural choices, design directions, trade-offs.invariant: Non-negotiable rules (e.g., "Use node:sqlite, zero native compiles").bug: Solved defects, regressions, and root-cause analyses.lesson: Tactical insights and framework discoveries.blocker: Active dependencies or external obstacles.
- Near-Duplicate Detection: If a proposed memory matches an existing active record ($\ge 0.85$ cosine similarity), the memory is saved with a warning proposing
revise(action: 'supersede', target_id: ...). This protects contrasting rules (e.g., "Allow CORS" vs "Do not allow CORS") while flagging twin facts. - Compulsory Invalidation Reasons: Calling
revise(action: 'invalidate')strictly requires a non-emptyreason. - Focused Audits:
nudgecaps findings at 3 with concrete evidence, rejectingevery_turntriggers to eliminate auditor nagware. - Span-Grounded Provenance & Drift Self-Healing: Passing
provenance: { file, locator, quoted_sentence }toremembercomputes a normalized SHA-256anchor_hashand line range (start_line..end_line). On subsequentretrieve(include_state: true)calls, the engine verifies the span on disk—automatically healing line numbers when code shifts above it, or flagging[DRIFTED]when the underlying code changes.
🧠 Embedding Reality & Offline Mode
- Zero-GPU Default: If neither Ollama nor an API key is present, the engine runs 100% offline using deterministic keyword extraction, recency scoring, and heuristic tag indexing.
- Local Ollama (Optional): Set
OLLAMA_URL="http://127.0.0.1:11434"withEMBED_MODEL="snowflake-arctic-embed2"(8,192-token context,1024dims, ~`664 MBVRAM, asymmetricquery:retrieval via/api/embed; also supportsqwen3-embeddingMRL1024d,nomic-embed-text, and legacybge-large`). - Remote Cloud (Optional): Set
OPENROUTER_API_KEY="sk-..."withEMBED_MODEL="baai/bge-large-en-v1.5"(or any1024-dim OpenRouter embedding model) for zero-local-VRAM embeddings.
🐘 When Do You Need PostgreSQL?
- Use SQLite (Default): Perfect for single developers, local IDE sessions, and projects with thousands of decisions—featuring compact
Float32Arraybinary vector blobs (4 KB/row) and an external-content Porter-stemmedFTS5lexical index. Zero Docker, zero setup. - Use PostgreSQL (
STORAGE_MODE=postgres): Required only when scaling to multi-agent swarms across different machines needing centralized persistence and server-side pgvector HNSW indexing.
🔄 Migration from v1.6 / v1.7
- Tool Aliases: Legacy tool names (
add_memory,search_memory,compile_state,supersede_memory,invalidate_memory,proactive_nudge) are automatically aliased to the 5 verbs with a deprecation notice. - Database Path: v1.7 used
.agent/memory.db. v1.8+ uses.agent/context.db. Runnpx krusch-context-mcp initto migrate. - See docs/MIGRATION.md for the complete mapping table.
🧩 Sibling Architecture
┌─────────────────────────────────────────────────────────────┐
│                 AI Coding Agent (Cursor / Claude)           │
└──────────────────────────────┬──────────────────────────────┘
                               │
               ┌───────────────┴───────────────┐
               ▼                               ▼
┌─────────────────────────────┐ ┌─────────────────────────────┐
│  krusch-context-mcp (v2.0)  │ │   krusch-git (External)     │
│   Project Memory & Steering │ │   Codebase RAG & AST Search │
│       (5 Canonical Verbs)   │ │      (7 Specialized Tools)  │
└──────────────┬──────────────┘ └─────────────────────────────┘
               │
               ▼
┌─────────────────────────────┐
│     .agent/context.db       │
│   (node:sqlite, Node ≥22)   │
└─────────────────────────────┘
Other specialized tools (krusch-nexus, krusch-law, krusch-biz) run as independent MCP servers in their own repositories.
💻 IDE Configuration
Cursor (.cursor/mcp.json)
{
  "mcpServers": {
    "krusch-context": {
      "command": "npx",
      "args": ["-y", "krusch-context-mcp"]
    }
  }
}
Claude Code
claude mcp add krusch-context -- npx -y krusch-context-mcp
Claude Desktop (claude_desktop_config.json)
{
  "mcpServers": {
    "krusch-context": {
      "command": "npx",
      "args": ["-y", "krusch-context-mcp"]
    }
  }
}
📊 External Benchmarks & 3-Category Verification Taxonomy
Ecosystem Verification Taxonomy: Evaluated across 335,000+ traces and 14 external benchmark suites, with published SHA-256 audit logs and reproducible evaluation artifacts — separating (1) CI-Verified Upstream PRs such as RouteWorks/RouterArena PR #169 (
0.7263across8,400/8,400live receipts —github-actions[bot]CI-verified upstream PR), (2) Uploaded & Queued Leaderboard Submissions ondolphinbench.ai(status: "queued"awaiting leaderboard acceptance, led byUUID c047b063at91.17%[547/600@$24.54] and open-weights stockUUID 288671adat54.17%[325/600@$0.00]), and (3) Independently Reproducible Clean-Room Evaluations with SHA-256-pinned audit logs in krush420/sovereign-g4-benchmarks.
Official DolphinBench (91.17% Queued UUID c047b063 @ $24.54, 90.67% Clean-Room Grounded v0.3 @ $30.54 & 57.33% Open-Weights @ $0.00) — Return on Memory
Evaluating all 600/600 multi-app workspace tasks across 13,539 conversational sessions (1,500,265 o200k_base tokens) under the official openai/gpt-5.6-sol judge (28 official 600-task evaluations = 16,800 official openai/gpt-5.6-sol traces across 6 model families: 8 uploaded & queued on dolphinbench.ai + 20 clean-room controls = 28/28 submission.validate passed), my byte-identical 0o444 read-only frozen Zero-LLM Raw-RAG (256/32-token windows) + Porter-FTS5 BM25 + snowflake-arctic-embed2 (1024d) 4-Way RRF node:sqlite store ($0.00 ingestion) achieves 91.17% (547/600 @ $24.54, Gemini 4 Argon Low — uploaded dolphinbench.ai submission UUID c047b063, status: "queued" awaiting leaderboard acceptance; exceeds current 70.67% published leaderboard entry in independent 600/600 evaluation), 90.67% (544/600 @ $30.54, Argon Low + Grounded v0.3 — self-run clean-room evaluation with highest Riley slice 181/200 = 90.50% and published SHA-256 audit logs; Argon Low Oracle@2 = 94.67% [568/600], Argon Oracle@4 = 96.83% [581/600], Global Oracle@28 = 98.33% [590/600]), 81.50% (489/600 @ $1.35, 1.57x faster, +10.83 pp > published 70.67% Mem0 entry @ 71.1x lower cost) model-matched on OpenAI GPT 5.6 Luna (High + Grounded) (81.33% Std.), and 57.33% (344/600 @ $0.00, Wave-6 krush420/gemma4-31b-sre-lora + Grounded — highest open-weights score in self-run 28-run evaluation; 56.67% Stock + Grounded; 54.17% [325/600] stock submission UUID 288671ad uploaded & queued on dolphinbench.ai; $0.00 Open-Weights Oracle@17 = 83.17% [499/600]):
| Agent Reader + Memory Substrate | Overall (600) |
Persona Breakdown (Morgan / Alex / Riley) |
Checks / Key Delta | Total Cost |
|---|---|---|---|---|
Sovereign Raw-RAG + Gemini 4 Argon (Low) |
91.17% (547/600, uploaded dolphinbench.ai submission UUID c047b063, status: "queued") |
95.5% (191) / 89.5% (179) / 88.5% (177) |
+20.50 pp (+123 tasks) > current 70.67% published Mem0 entry in independent 600/600 eval · Mech 92.22% (1,221/1,324) · Sem 93.62% (558/596) · 35.38s |
$24.54 ($0.00 ingest, 57.1% cache hit, ~3.9x cheaper) |
Sovereign Raw-RAG + Gemini 4 Argon (Low) + Grounded v0.3 |
90.67% (544/600, clean-room eval, highest Riley slice 90.50%) |
94.5% (189) / 87.0% (174) / 90.5% (181, highest Riley slice) |
Argon Low Oracle@2 = 94.67% (568/600) · Argon Oracle@4 = 96.83% (581/600) · 89.17% (535) v0.2 control · +21 unique wins vs. Std. |
$30.54 ($23.92 v0.2, SHA-256 665fb7ad...) |
Sovereign Raw-RAG + Gemini 4 Argon (Medium) |
89.17% (535/600, queued UUID 29389157) |
92.0% (184) / 87.0% (174) / 88.5% (177) |
Mech 89.77% (1,193/1,329) · Sem 92.22% (545/591) · 55.27s |
$24.57 (56.5% cache hit) |
Sovereign Raw-RAG + GPT 5.6 Luna (High, + Grounded / Std. / + 2PC) |
81.50% (489) / 81.33% (488) / 80.50% (483) |
87.0% (174) / 78.5% (157) / 79.0% (158) (+Grounded) · 176/156/156 (Std.) |
+10.83 pp (+65 tasks) > published 70.67% Mem0 entry @ 71.1x lower cost · 30.03s (1.57x faster) · Oracle@2 = 89.33% (536/600), Luna Oracle@5 = 91.83% (551/600) |
$1.35 / $1.38 (62.9% cache hit) |
Sovereign Raw-RAG + Gemini 4 Argon (Turn-0 Briefing-Only, Med / Low) |
79.17% (475) / 78.00% (468) |
86.0%/82.5% · 77.5%/77.5% · 74.0%/74.0% |
0 follow-up search_persona_memory calls (26.93s / 21.49s; 2×2 $\Delta\Delta = +3.17\text{ pp}, p = 0.0320$) |
$16.91 / $15.76 (+7.33 pp > Mem0 @ 6.1x lower cost) |
Sovereign Raw-RAG + GPT 5.6 Luna (Low, Std. / + 2PC) |
76.67% (460/600) / 76.50% (459/600) |
85.0% (170) / 72.5% (145) / 72.5% (145) (Std. Harness) · 176/144/139 (+2PC) |
+6.00 pp (+36 tasks) > published 70.67% Mem0 entry @ 87.4x lower cost · Luna Oracle@5 = 91.83% (551/600) · 40.85s |
$1.10 / $1.12 |
Current Published Leaderboard Entry: Hermes + GPT 5.6 Luna + Mem0 |
70.67% (424/600) |
78.0% (156) / 66.0% (132) / 68.0% (136) |
37.69s median · Current highest published dolphinbench.ai entry (Supermemory 59.17% @ $345.64) |
$96.21 |
krush420/gemma4-31b-sre-lora & Google Gemma 4 31B (30.7B Dense Q4_K_M) |
57.33% (344, highest open-weights in 28-run self-run evaluation) / 56.67% (340, Stock+Grounded) / 54.17% (325, uploaded & queued UUID 288671ad) |
74.5% (149) / 51.5% (103) / 46.0% (92) (Wave-6+Grounded) · 146/97/97 (Stock+Grounded) · 144/95/86 (Stock) |
54.83% (329) Wave-5 · 53.67% (322) Wave-4 · 52.00% (312) OFF · Gemma 4 Oracle@6 = 71.83% (431/600) · Beats ALL 8 non-GPT-5.6-Luna cloud stacks up to $1,830.57 |
$0.00 |
krush420/qwen3-coder-30b-sre-lora & Qwen3-Coder-30B-A3B (3.3B active) |
43.00% (258, highest Qwen/MoE +Grounded) / 42.67% (256, Wave-4) / 42.00% (252, +2PC & Stock) |
62.5% (125) / 31.5% (63) / 35.0% (70) (Wave-4+Grounded) · 111/70/75 (Wave-4) |
INV-STACK-10 2PC: -95.2% dup MCP calls (42 -> 2) & 30B Oracle@2 = 50.33% · 38.50% (231) Wave-6 control · 30B Oracle@5 = 61.17% (367/600) |
$0.00 |
gpt-oss:120b Wave-4 QLoRA+DPO / Stock (5.1B active) |
39.50% (237) / 39.17% (235) |
54.5% (109) / 31.5% (63) / 32.5% (65) (Wave-4) |
+7.33 pp Raw-RAG + 4-Way RRF lift over raw turns (9.62s Stock / 16.83s Wave-4) |
$0.00 |
Qwen3-Coder-Next-80B (38.50%) · Qwen2.5-Coder-32B (35.33%) · Hermes-4-14B (34.50%) |
231 / 212 / 207 of 600 |
104/68/59 · 97/59/56 · 99/57/51 |
Scaling & domain controls: Gemma 4 31B > Qwen2.5-Coder-32B by +22.00 pp Wave-6 Grounded / +18.83 pp Stock ($p = 1.35 \times 10^{-16}$); 14B ties 32B ($p = 0.729$) |
$0.00 |
Hermes-3-Llama-3.1-8B Wave-4 LoRA+DPO (Q4_0) |
18.33% (110/600) |
26.0% (52) / 14.5% (29) / 14.5% (29) |
15.7x lift over 1.17% stock (Ollama .System fix + BF16 LoRA+DPO) |
$0.00 |
- Four Return on Memory Scaling Laws & 4-Vertex Pareto Frontier: (1)
98.33%(590/600:Morgan 196,Alex 199,Riley 195)Global Oracle@28retrieval sufficiency (<= 1.67%zero-LLM Raw-RAG indexing miss) across the frozen0o444SQLite store (94.67%[568/600]Argon Low Oracle@2,96.83%[581/600]Argon Oracle@4, and83.17%[499/600]$0.00Open-WeightsOracle@17(+12.50 ppabove published70.67%Mem0entry)) and controlled memory-vs.-reader attribution via model-matchedGPT 5.6 Luna (High)at81.50%(489/600Grounded) /81.33%(488/600Std.) @$1.35(52.0%[+10.67 pp, $p = 5.96 \times 10^{-9}$] of my+20.50 pplead over the70.67%publishedMem0baseline comes purely from$0.00Raw-RAG memory,48.0%[+9.83 pp] fromArgon Low), establishing a 4-vertex100%Sovereign Raw-RAGPareto frontier ($0.00[57.33%gemma4-31b-sre-lora/54.17%Stock] →$1.10[76.67%Luna Low] →$1.35[81.50%Luna High + Grounded] →$24.54[91.17%Argon Low]); (2)4.19xsuperlinearLBF=4+multiplier (89.33%[67/75]Argon Lowvs.21.33%[16/75]30B&Gemma 4 31BStock,16.75xvs.8B); (3) Scale-dependent Goldilocks reasoning &+22.00 pp/+18.83 pp($p = 1.35 \times 10^{-16}$) post-training domain specialization (2×2Thinking × Search$\Delta\Delta = +3.17\text{ pp}, p = 0.0320$ on Argon;+2.17 ppthinking lift,+2.50 ppGrounded lift, &+3.17 ppWave-6 QLoRA+DPO lift onGemma 4 31B); and (4) Flatter corpus-entropy decay (-4.00 ppArgon Low + Grounded v0.3[94.5%→90.5%, highestRileyslice181/200] /-7.00 ppArgon Low/-3.50 ppArgon MediumMorgan→Rileyvs.-10.00 pponMem0[78.0%→68.0%,-12.00 pptoAlex66.0%] and-32.50 pponMiniMax M3 + Hindsight). - Verified Upstream Queue & Open Artifacts:
8sovereign submission.ziparchives (Argon LowUUIDc047b063-822c-49fb-8b36-27c3763d6ca7[91.17%/547/600], SHA-25680a199a60aef65f0d963d0402a2e3b0af99b82ed63e2f422001234b6ed770f0b;Argon MediumUUID29389157-b01b-42b5-8193-17d9a496f580[89.17%], SHA-2569a7fa41fb3d1cf5f71f0c3cf74a0c97f8f39d50e26a7dd484c323f7719ecb7a0; uploaded & queued open-weights stockGemma 4 31BUUID288671ad-afe0-40a3-93af-b834c9bbd306[54.17%/325/600], SHA-2562a23c2a023473a6642f5a61f1d99ff569f3d50ac53e60576f8195eef659c254b; plus30b_wave4,30b_stock,120b_wave4,120b_stock, and8b_wave4) holdstatus: "queued"ondolphinbench.aiawaiting maintainer merge (dolphinbench.ai/leaderboard/results.jsoncurrently lists the13commercial cloud baselines), and all28/28official archives (8queued flagships +20clean-room controls) passedsubmission.validate(error_code: null). Read Paper #27 (HTML) · Paper #27 (PDF) · Paper #26 (Local AI Ablation) · `49` SHA-256 Hugging Face Audit Logs across `64` files (`48` raw JSON + `1` live PR #169 receipt bundle, `95/95` ecosystem gates) (`krush420/sovereign-g4-benchmarks`).
Official Snap LoCoMo (ACL 2024, 1,540/1,540 QA Probes)
- Zero-gaming, clean-room evaluation across all
10multi-month conversations (5,882turns,1,515256/32-token Raw-RAG windows) and1,540/1,540standard Category 1–4 QA probes (snap-research/locomoSHA-25679fa87e9...ea698ff4) using the unmodifiedSovereignMemoryStore(0o444read-only frozen SQLite stores,$0.00/0-LLM ingestion via localsnowflake-arctic-embed21024d+ Porter FTS5 4-Way RRF) and verbatimmem0ai/mem0@aae5989eANSWER_PROMPT_ZEP+ACCURACY_PROMPT(gpt-4o-minitemperature=0.0judge):argon_matched(9,983meancl100ktokens,3.01×compression):90.26%(1,390/1,540) judged accuracy (94.17%Single-Hop,92.83%Temporal,84.04%Multi-Hop,65.62%Open-Domain),95.77%ground-truthdia_idevidence recall (98.87%Single-Hop,97.98%Temporal),63.97%official Porter-stemmed token F1,181.8 msmedian local retrieval, and+19.86 ppover LivingBrain / SuperLocalMemory V3.3's zero-LLM mode (70.4%) (trace_argon_matched.jsonlSHA-25668363e5f7c6cf733b42681c6e73911b129e71a43a41ac385cf56daf96a80d70d).argon_tight(4,465meancl100ktokens,6.73×compression —<0.5×peer token budget):89.68%(1,381/1,540) judged accuracy,91.05%dia_idrecall (96.37%Single-Hop,95.25%Temporal),63.11%official F1,186.4 msmedian retrieval, and92.66%(1,427/1,540)Oracle@2across both frozen runs (trace_argon_tight.jsonlSHA-256e48f3cc00f690eda2d8345283fc822f05527eb95844aa923001f74a2b82f87f1;5/5zero-leakage &BlindMappingGuardchecks passed; full report).
Official ICLR 2026 BEAM (100K–10M Tokens, 2,000/2,000 Probes)
- Closed-system full-suite evaluation across all
100conversations (~178.34Mtokens) and2,000/2,000questions (100K,500K,1M,10Msplits) onnode:sqlite+snowflake-arctic-embed2(8Kctx) in a fixed~8Kprompt budget: reaches92.58%(100K) &93.00%(10MIE) recall (78.67%4-split weighted), exhibits zero E2E QA degradation from100K→1M(70.60%→71.82%→72.86%onhermes3), and outperforms cloudpast.dev(openai/gpt-5.6-luna) on Contradiction Resolution across all4/4splits and on10MMulti-Session Reasoning across both cross-family referees (29.54%/38.33%vs.28.17%) with10/10zero-leakage verification (full report).
📚 Documentation & Specifications
- Canonical Tool Reference: Generated directly from live schemas (
npm run docs:generate). - Architecture & Failure Modes: 2-page specification covering schemas, indexes, and
v2.0.0multi-scale retrieval invariants. - Setup & Operations Guide: Zero-Docker setup and optional configurations.
- Migration Guide: Step-by-step v1.5 → v1.6 → v1.7 → v1.8 → v1.9.0 → v2.0.0 mapping.
- Episodic Memory Guide: Deep dive into the closed taxonomy and lifecycle.
- Changelog: Version release notes.
- Official Snap LoCoMo Empirical Report: Clean-room
1,540/1,540-probe ACL 2024 evaluation (90.26%matched /89.68%tight /92.66%Oracle@2,95.77%dia_idrecall,$0.00zero-LLM ingest) and JSON receipts (benchmarks/locomo/). - Official ICLR 2026 BEAM Empirical Report: Full
100-conversation (~178.34M-token),2,000/2,000-probe methodology, per-ability tables, and10/10zero-leakage verification gates. - Official DolphinBench Whitepapers & Clean-Room Audit Logs: Paper #27 (HTML), Paper #27 (PDF), Paper #26, and all
28OfficialDolphinBenchruns (16,800officialgpt-5.6-soltraces across6model families,8uploaded & queued ondolphinbench.ai+20clean-room controls =28/28submission.validatepassed — led by91.17%[547/600@$24.54] uploadeddolphinbench.aisubmissionUUID c047b063-822c-49fb-8b36-27c3763d6ca7[status: "queued"awaiting leaderboard acceptance; exceeds current70.67%published leaderboard entry in independent600/600evaluation],90.67%[544/600@$30.54] self-run clean-roomArgon Low + Grounded v0.3[highestRileyslice181/200 = 90.50%, published SHA-256 audit logs],89.17%Argon MediumqueuedUUID 29389157-b01b-42b5-8193-17d9a496f580, &57.33%[344/600@$0.00] Wave-6krush420/gemma4-31b-sre-lora+Grounded[highest open-weights score in self-run 28-run evaluation;56.67%Stock+Grounded;54.17%(325/600) stock submissionUUID 288671ad-afe0-40a3-93af-b834c9bbd306uploaded & queued ondolphinbench.ai];Global Oracle@28 = 98.33%,$0.00Oracle@17 = 83.17%;49SHA-256 Hugging Face audit logs across64files) in krush420/sovereign-g4-benchmarks. - Evaluation Baseline Notes: Preliminary benchmark fixtures and token-budget metrics.
🧪 Testing
# Run full unit & contract test suite (100% SQLite, zero Docker)
npm test

# Check storage and memory health
npm run health
License
MIT © kruschdev
Установка Krusch Context
У этого сервера нет опубликованного пакета — он собирается из исходников. Открой репозиторий и следуй инструкции в README.
▸ github.com/kruschdev/krusch-context-mcpFAQ
Krusch Context MCP бесплатный?
Да, Krusch Context MCP бесплатный — установка в пару кликов через Unyly без оплаты.
Нужен ли API-ключ для Krusch Context?
Нет, Krusch Context работает без API-ключей и переменных окружения.
Krusch Context — hosted или self-hosted?
Self-hosted: сервер запускается локально на твоей машине командой из раздела установки.
Как установить Krusch Context в Claude Desktop, Claude Code или Cursor?
Открой Krusch Context на unyly.org, выбери вкладку своего клиента (Claude Desktop, Claude Code, Cursor) и нажми Install — конфиг сгенерируется автоматически, без правки JSON.
Похожие MCP
GitHub
PRs, issues, code search, CI status
 автор: GitHub
Filesystem
Secure file operations with configurable access controls.
Memory
Knowledge graph-based persistent memory system.

Unyly Deploy
Deploy sites and MCP servers to Unyly straight from your AI agent
 автор: Unyly
Amap Maps Mcp Server
MCP server for using the AMap Maps API
 автор: duxiaohui
PayMCP
Lightweight payments layer for MCP servers: turn tools into paid endpoints with a two-line decorator. [PyPI](https://pypi.org/project/paymcp/) · [npm](https://w
 автор: blustAI
Server For Power BI
Enables exploring Microsoft Fabric / Power BI workspaces and semantic models, and executing ad-hoc DAX queries.
 автор: Mitsubishi-Fuso
Gpt Image 2 Mcp
RunAPI GPT Image 2 MCP server for image generation: create tasks, poll results, and check pricing across 1 model from Claude Code, Codex, Cursor, and VS Code.
 автор: runapi-ai
Template MCP Server
A CLI tool to create a new Model Context Protocol server project with TypeScript support, dual transport options, and an extensible structure
 автор: mcpdotdirect
Supabase
Database, auth and storage
 автор: Supabase
Compare Krusch Context with
Не уверен что выбрать?
Найди свой стек за 60 секунд
Автор?
Embed-бейдж для README
Похожее
Все в категории development